 In our experience, server monitoring is a critical component of infrastructure performance management. Unplanned server downtime can cause significant disruptions to your applications and users, especially without real-time visibility into uptime and performance.
A server monitoring tool like Dotcom-Monitor delivers instant alerts when problems arise, enabling your team to act quickly before issues affect the user experience.
With a wide variety of tools available, we’ve found the right choice depends on factors like ease of use, alerting capabilities, integration options, and how well the tool scales with your infrastructure. Those are the criteria we used to review each of the 25 tools below. If you already know your use case, start with our top picks; if not, the full reviews and the comparison table cover every tool side by side.
Our Top Picks at a Glance
Short on time? Here is the tool we’d shortlist first for each common server monitoring job, with a runner-up to compare it against. Each pick links to its full review below.
| Use case | Our pick | Why we picked it | Also consider |
|---|---|---|---|
| Web server uptime and external monitoring | Dotcom-Monitor | Checks availability and response time from 25 global locations (30+ on Enterprise), no agent needed | Uptime Kuma (self-hosted) |
| Windows server monitoring | SolarWinds SAM | Templates for IIS, SQL Server and Active Directory, plus agentless WMI | PRTG, ManageEngine OpManager |
| Linux server monitoring | Checkmk | Auto-discovers every service on a new host; agents for Linux and Unix variants | Zabbix, Icinga |
| Remote server monitoring (RMM) | NinjaOne | Built-in remote access and scripted remediation on alert | Site24x7 |
| Real-time server monitoring | Netdata | Per-second metrics with on-agent anomaly detection | Datadog |
| Application server monitoring | AppDynamics | Ties server performance to specific business transactions | Dynatrace, New Relic |
| Free and open source | Zabbix | No per-host licensing at any scale | Prometheus, LibreNMS |
| Kubernetes and cloud-native | Prometheus | The de facto metrics standard for Kubernetes | Grafana Cloud, Datadog |
| Hybrid enterprise IT | LogicMonitor | Agentless collectors across on-prem and cloud, with Edwin AI | Dynatrace |
| Small teams on a budget | Site24x7 | Managed all-in-one monitoring from $9/mo | New Relic free tier |
How We Evaluated These Tools
We built this guide as a structured comparison, not a popularity list. For each of the 25 tools, we:
Confirmed what it actually monitors. We read the vendor’s current documentation to establish whether a tool collects host metrics, polls network devices, traces applications, or checks availability from the outside, and how it collects data (agent, agentless, pull, push or synthetic checks).
Checked every pricing page in September 2026. We recorded list prices, billing basis, free tiers and trial lengths, and dated each pricing block. Vendors change prices often, so treat the figures as a starting point and confirm on the vendor’s site before you buy.
Compared the same criteria for every tool. Alerting and integrations, AI or anomaly detection, deployment model (SaaS or self-hosted), and how cost scales as you add hosts, sensors or users.
Read what users report. We went through reviews on G2, Capterra, Gartner Peer Insights, TrustRadius and PeerSpot, plus sysadmin community discussions, to find the strengths and complaints that come up again and again. Each tool’s “Our take” summarizes those patterns in our own words.
This guide is written by Matthew Schmitz, Director of Load and Performance Testing at Dotcom-Monitor, who leads the engineering team behind our load and performance testing products.
A note on bias: Dotcom-Monitor is our product, and it is listed first. We’ve held it to the same criteria as every other tool, including where it falls short: it checks availability and performance from the outside, and its host metrics come from a separate collector agent, so it does not replace a deep infrastructure or APM platform. After #1, the numbering is not a ranking. Use the “best for” label on each tool and the top picks table to find the right fit.
What Is Server Monitoring?
Server monitoring is the process of continuously tracking the performance and availability of your IT infrastructure to ensure servers are running as expected. When issues occur, a monitoring tool immediately alerts your team so they can step in quickly, minimize user impact, identify the root cause, and prevent recurrence.
In our experience, finding the right tool can feel overwhelming. Some solutions offer exactly what you need; others include far more than you will ever use. What we’ve found matters most is that your chosen tool accurately tracks the metrics that drive reliability – CPU load, memory usage, storage, and network performance – and fits the way your team actually works.
What Server Metrics Should You Monitor?
Knowing which metrics to track is the foundation of effective server monitoring. Here are the key ones we recommend, because they help you catch problems early and keep systems running efficiently:
CPU usage shows how hard your server’s processor is working. Consistently high CPU utilization can indicate that your server is struggling to handle its workload, potentially leading to slowdowns or crashes.
Memory usage tracks how much RAM is in use. Excessive memory consumption causes sluggish performance and can ultimately result in downtime.
Disk space and I/O covers both available storage and read/write throughput. Low disk space or degraded I/O performance can seriously impair application behavior.
Network performance – including bandwidth, traffic volume, and latency – helps you identify bottlenecks or connectivity issues that slow server response times.
The 25 Best Server Monitoring Tools for 2026, Reviewed
Here is how all 25 tools compare on metrics coverage, data collection, AI features and free options (pricing and features as of September 2026):
| Tool | Type | CPU/Mem/Disk/Net | Data Collection Method | AIOps / Anomaly Detection | Free Tier / Trial | Best For |
|---|---|---|---|---|---|---|
| Dotcom-Monitor | Synthetic Monitoring SaaS | Yes – via MetricsView agent | External synthetic checks from 25 locations (30+ on Enterprise); Private Agents inside networks; MetricsView collector for Windows, Linux (collectd) and SNMP metrics | No – AI Data Analysis (beta) explains failed sessions | Free forever plan (25 targets) + 30-day full-feature trial | Web server uptime, synthetic, and API monitoring |
| Site24x7 | Cloud Infrastructure SaaS | Yes | Agent + Agentless (WMI, SNMP) | Yes – AIOps (higher tiers) | Free plan (50 resources) + 30-day trial | All-in-one cloud monitoring |
| NinjaOne | RMM Platform | Yes | Agent (Windows, macOS, Linux) | No | 14-day free trial | MSPs and IT service teams |
| Datadog | Observability SaaS | Yes | Agent with 1,000+ integrations | Yes – Watchdog AI (Enterprise) | 14-day free trial | Cloud-native DevOps and SRE teams |
| Dynatrace | Full-Stack Observability SaaS | Yes | OneAgent (auto-instrumentation, no manual config) | Yes – Davis AI causation engine | 15-day free trial | Enterprise full-stack observability |
| AppDynamics | APM Platform (Splunk AppDynamics, Cisco) | Yes | Per-runtime language agent | Yes – dynamic baseline alerting | 15-day free trial | App-centric infrastructure monitoring |
| SolarWinds SAM | Commercial Self-Hosted (on-prem or your cloud) | Yes | Agent + Agentless (WMI) | No | 30-day full trial | On-prem Windows and hybrid infrastructure |
| Zabbix | Open Source | Yes | Agent + SNMP / IPMI / JMX / SSH / Telnet | No | Free | Large-scale self-managed infrastructure |
| Prometheus | Open Source TSDB | Yes – via node_exporter / windows_exporter | Pull-based (exporters scrape targets) | No | Free | Cloud-native and Kubernetes environments |
| Grafana Cloud | Managed Observability SaaS | Yes – via Grafana Alloy agent | Pull (Prometheus-scrape) + Push (OTLP) | No | Free tier (active series + retention limits) | Unified metrics, logs, traces, and profiles |
| New Relic | Observability SaaS | Yes – dedicated Infrastructure agent | Agent (Infra agent separate from APM) | Yes – Applied Intelligence alert correlation | Free tier: 100 GB/mo + 1 full-platform user | Full-stack observability, SMB to enterprise |
| LogicMonitor | Cloud Monitoring SaaS | Yes | Agentless LM Collector (SNMP, WMI, JMX, REST) | Yes – Edwin AI | 15-day free trial | Hybrid infrastructure at enterprise scale |
| ManageEngine OpManager | Commercial Self-Hosted | Yes | Agentless (SNMP v1/v2c/v3, WMI) + optional agents | No | Free edition (3 devices) + 30-day trial | On-prem server and network operations |
| PRTG Network Monitor | Commercial Self-Hosted | Yes | Agentless (SNMP, WMI, REST, Flow) | No | Freeware (100 sensors) + 30-day trial | SMB to mid-size self-hosted monitoring |
| Uptime Kuma | Open Source, Self-Hosted | No – reachability and response time only | Agentless active checks (HTTP, TCP, ping, DNS) + push heartbeats | No | Free (MIT), self-hosted | Simple self-hosted uptime and status pages |
| Elastic Observability | Source-Available Stack (ELv2) | Yes | Elastic Agent with System integration | Yes – ML anomaly detection (Platinum+) | Free tier on Elastic Cloud | Unified logs, metrics, and APM in one cluster |
| Icinga | Open Source | Yes | Agent (Icinga agent) + Agentless (SNMP, SSH) | No | Free | Config-as-code and IaC-driven monitoring teams |
| Nagios | Open Source / Commercial | Yes | NRPE (active, inbound TCP 5666) + NSCA (passive) | No | Core: free / XI: Free Edition + 30-day trial | Traditional sysadmin and IaC-managed environments |
| Pandora FMS | Open Source / Commercial | Yes | Agent + Agentless (SNMP, WMI, SSH) | No | Free trial | Hybrid on-prem environments |
| Checkmk | Open Source / Commercial | Yes | Checkmk agent + SNMP | No | Community Edition free + 30-day trial | Mid-to-large self-managed infrastructure |
| Sensu Go | Open Source (event-driven framework) | Yes | sensu-agent with dynamic runtime assets | No | Free tier (up to 100 nodes) + 14-day trial for Pro/Enterprise | DevOps, IaC, and ephemeral infrastructure |
| WhatsUp Gold | Commercial Self-Hosted | Yes – via SNMP and optional agent | Agentless (SNMP) + Agent | No | Free Edition (10 devices) + free trial | Network-centric IT operations teams |
| LibreNMS | Open Source | Yes – primarily via SNMP | Agentless (SNMP autodiscovery) | No | Free (self-hosted); managed hosting via cloud providers at infrastructure cost | Network and server ops teams using SNMP |
| Netdata | Open Source / SaaS | Yes | Lightweight agent (per-second collection) | Yes – on-agent ML anomaly detection | Free agent + free Community cloud tier + 14-day Business trial | Real-time host and container performance monitoring |
| Centreon | Open Source / Commercial | Yes | Agent + Agentless (SNMP, SSH) | No | Open source + free self-hosted IT 100 (100 hosts) | Distributed on-prem monitoring with pollers |
1. Dotcom-Monitor: best for web server uptime, synthetic and API monitoring
We’ll start with our own platform. Dotcom-Monitor is a cloud-based monitoring platform for websites, APIs, servers and web applications, operating since 1998. It tracks server uptime and response times from the end-user perspective, from 25 global monitoring locations on subscription plans (30+ on Enterprise). Its core strength is synthetic monitoring, proactively simulating user interactions via the EveryStep Web Recorder to detect availability and performance issues before real users encounter them, along with API monitoring for REST, SOAP, and JSON/XML backend services. Protocol-level checks cover email servers (SMTP, POP3, IMAP), FTP servers, TCP ports, DNS and ICMP ping.
It also covers port monitoring: scheduled TCP connect checks against any host and port from global monitoring locations or a private agent.
Use website uptime monitoring alongside server checks to verify that a reachable host is serving the expected page.
For host-level metrics, the Performance Counters platform (MetricsView) adds a collector agent that gathers Windows Performance Counters (CPU, memory, cache, disk), Linux metrics through collectd, and SNMP v1 to v3 data from network devices. Private Agents do a different job: they run synthetic checks from inside your network, behind the firewall. Alerting is supported via SMS, email, phone call, WhatsApp, Slack, PagerDuty, Microsoft Teams, ServiceNow, and more than 20 other integrations on paid plans. Performance waterfall reports provide HAR-style breakdowns for diagnosing slow page loads or API responses at the element level, and the optional AI Data Analysis feature (beta) reads a waterfall report and explains the likely cause of a failed or degraded session in plain language.
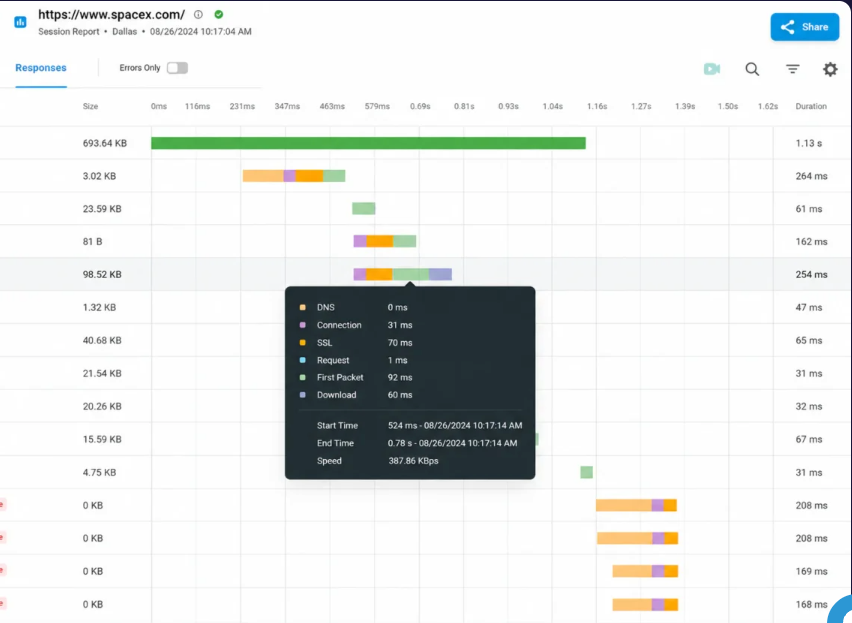
Our take: Dotcom-Monitor is the right pick when the question is “can users reach this server, and how fast does it respond?” rather than “why is this host’s CPU high?”. Teams that need deep process, log or code-level visibility should pair it with one of the agent-based platforms below.
Pricing
Dotcom-Monitor is trusted by Comcast, Dell, Volvo, and 10,000+ others. Free: $0 forever (25 targets, 5-min frequency, 2 locations, email alerts, basic support). Subscriptions: from $19.99/month, priced by monitoring platform, number of targets and check frequency (up to 100 targets, down to 1-min frequency, 25 locations, 20+ integrations, Private Agents, standard support). Enterprise: custom (unlimited targets, 30+ locations including Premium Locations, SSO, MFA, 24/7 priority support). 30-day full-feature trial, no credit card required (as of September 2026).
| Pros | Cons |
|---|---|
| No agent needed for external checks – 25 locations (30+ on Enterprise) | 1-minute minimum check frequency |
| Multi-step transaction monitoring via EveryStep | Free plan limited to 25 targets and 2 locations |
| Optional MetricsView collector adds Windows, Linux and SNMP host metrics | Cost scales with target count and check frequency |
| 20+ alert channels including WhatsApp, PagerDuty, Teams |
Start monitoring in minutes. Dotcom-Monitor’s 30-day free trial gives you full access to all subscription features – no credit card required. Monitor websites, APIs, and user journeys from 25 global locations with 1-minute check frequency and 20+ alert integrations. Start Your Free 30-Day Trial →
2. Site24x7: best for budget all-in-one monitoring
In our review, Site24x7 stood out as a flexible choice for organizations running diverse server environments, thanks to its cloud-based infrastructure monitoring. It monitors real-time performance metrics including uptime, CPU usage, disk utilization, and memory, and supports virtualization monitoring for platforms such as Microsoft Hyper-V and VMware. Supported server operating systems include Windows, Linux, macOS, FreeBSD, IBM AIX and Solaris. Beyond agent-based collection, Site24x7 also supports agentless server monitoring via WMI and SNMP through an On-Premise Poller installed in your network, giving teams flexibility in how they instrument their environments. The Enterprise plan adds AI-based anomaly detection and event correlation, and on-call schedules with alert escalation are built in.
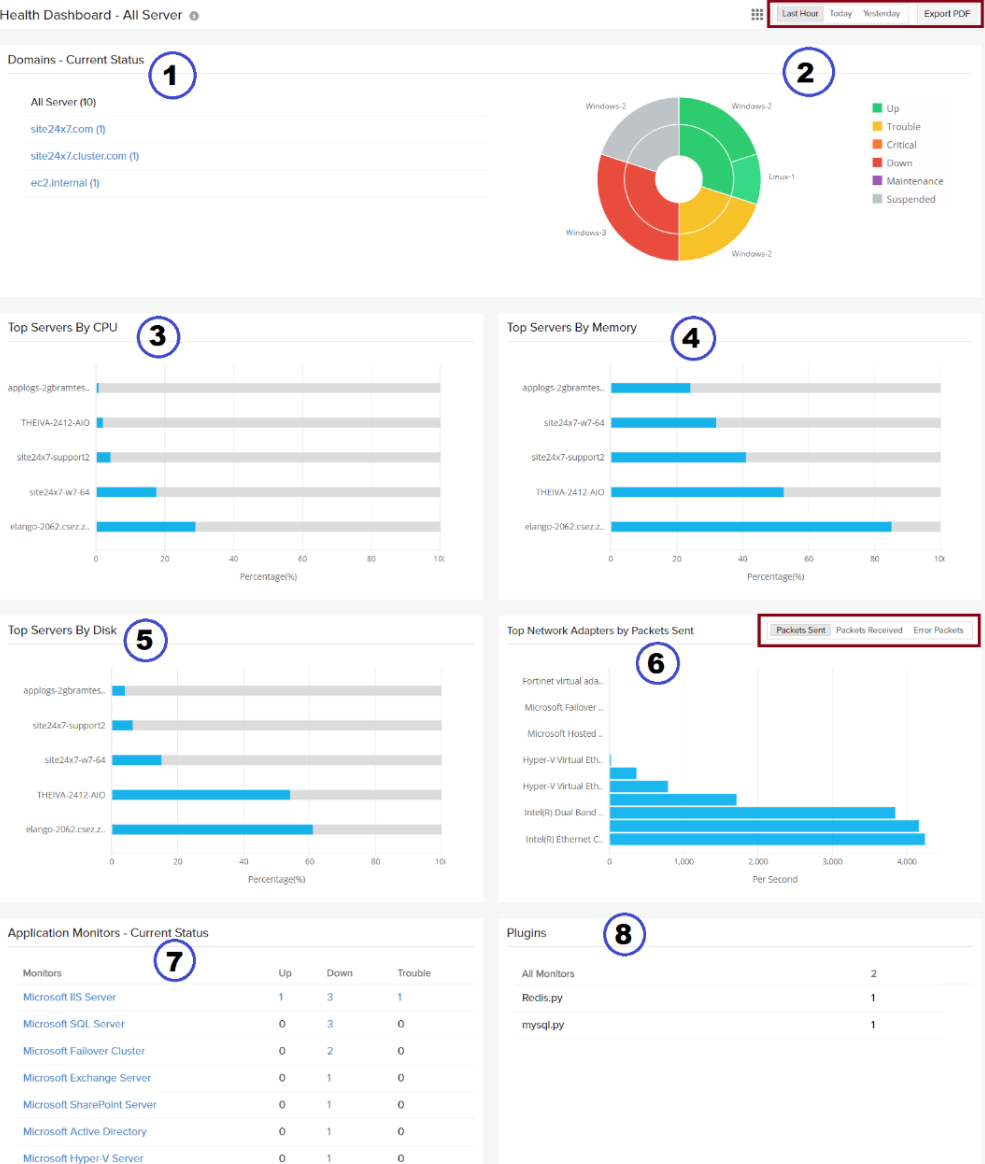
Our take: Reviewers on Capterra and G2 consistently credit Site24x7 with covering servers, websites, networks and cloud from one console at a fair price. The most common complaints are a dense interface and add-on licensing that takes time to understand.
Pricing
Lite: $9/mo · Professional: $42/mo · Enterprise: from $625/mo (billed annually; monthly billing $10 and $49). Free plan for up to 50 resources. 30-day free trial, no credit card required (as of September 2026).
| Pros | Cons |
|---|---|
| Covers servers, networks, websites, apps, and cloud in one platform | AI anomaly detection and event correlation only on Enterprise |
| Agent-based and agentless (WMI, SNMP) collection | Outbound connectivity required from monitored servers |
| Built-in on-call schedules and alert escalation | Interface can feel complex at scale |
| Free plan covers up to 50 resources | Mobile app less capable than the web console |
3. NinjaOne: best for remote server monitoring (RMM)
NinjaOne is a Remote Monitoring and Management (RMM) platform that, in our assessment, excels in remote server monitoring. It supports Windows, macOS, and Linux servers, allowing teams to track server health, uptime, and performance metrics from a single interface. Remote desktop access to monitored servers is built directly into the platform, and automated remediation scripts can be triggered on alert conditions, reducing the need to switch between separate tools during an incident. NinjaOne also includes software inventory and license tracking alongside monitoring, offers its own ticketing, and integrates with PSA and ITSM tools including ConnectWise, Autotask, HaloPSA, and Freshservice.
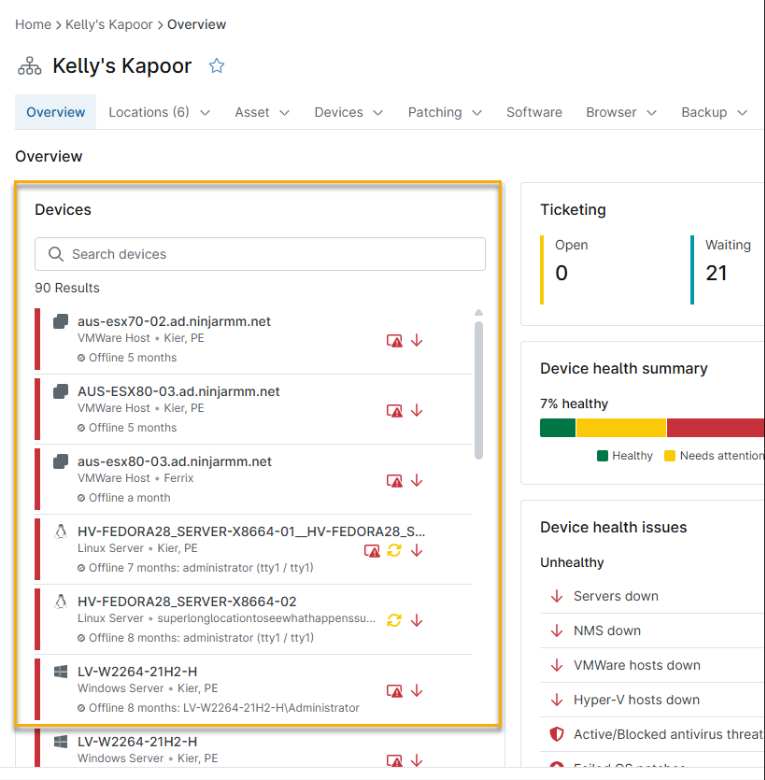
Our take: Users on Capterra and G2 praise NinjaOne’s clean interface, fast remote access and automated patching, which several say saves technicians hours each week. The recurring criticism is shallow reporting and dashboard customization for complex needs.
Pricing
Per-device pricing, quote required; the vendor cites roughly $1.50 to $3.75 per device/mo depending on volume. Monthly or annual billing. 14-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| Remote desktop access built into the platform | Quote required; only an indicative per-device range is published |
| Automated remediation scripts trigger on alert conditions | Reporting less advanced than dedicated monitoring tools |
| Software inventory and license tracking included | Not designed for deep APM or IaC monitoring |
| Own ticketing, plus ConnectWise, Autotask, HaloPSA, Freshservice | Better for IT/MSP than DevOps/SRE workflows |
4. Datadog: best for cloud-native DevOps and SRE teams
Datadog is a widely adopted observability platform with 1,000+ integrations that provide full-stack visibility across infrastructure, applications, and logs. It offers highly customizable dashboards that let DevOps and SRE teams view real-time metrics, logs, and traces side by side. We found its APM capabilities make it particularly strong for organizations running cloud-native and containerized workloads where correlating infrastructure metrics with application performance data is essential. Many integrations ship with the Datadog Agent and are switched on with a short configuration file, while Autodiscovery configures common services automatically in container environments. The Host Map and Live Containers views show every monitored host and container, and on the Enterprise tier, Live Processes adds process-level visibility. Watchdog, Datadog’s AI anomaly detection layer (also on the Enterprise tier), continuously surfaces unusual patterns across monitored signals without requiring manual alert configuration.
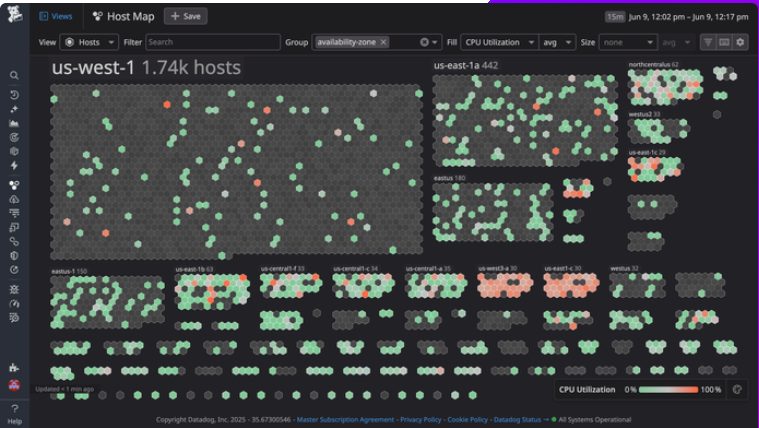
Our take: Reviewers on Gartner Peer Insights and PeerSpot value having metrics, traces and logs in one place, which speeds up incident response. The two complaints we saw most often: costs that grow quickly and are hard to forecast, and noisy alerts until monitors are tuned.
Pricing
Infrastructure (per host/mo): Free $0 (5 hosts, 1-day retention) · Pro $15 billed annually ($18 on-demand) · Enterprise $23 billed annually ($27 on-demand). DevSecOps bundles $22 to $34/host annually. APM, Logs and Synthetics billed separately. 14-day free trial, no credit card required (as of September 2026).
| Pros | Cons |
|---|---|
| Unified metrics, APM traces, logs, and synthetics in one platform | Per-host + per-module billing escalates sharply at scale |
| Host Map, Live Containers and Live Processes (Enterprise) | Full stack requires enabling multiple separately billed products |
| 1,000+ integrations; Autodiscovery configures common services | 15-month default retention; longer costs extra |
| Watchdog AI (Enterprise) surfaces anomalies without manual rules | Tuning cardinality at scale requires experience |
5. Dynatrace: best for automated root-cause analysis at enterprise scale
Dynatrace is a commercial full-stack observability platform that, as we saw in our review, covers infrastructure monitoring, APM, and digital experience management in a single product. Its OneAgent, a single installer deployed on each monitored host, automatically discovers and instruments the server, collecting CPU usage, memory, disk I/O, network throughput, and individual process resource consumption without requiring manual configuration of checks or exporters. The full-stack topology of all monitored entities is continuously maintained as a Smartscape map, providing a live view of relationships between hosts, processes, services, and applications, and the Davis AI engine uses that topology to group related events into a single problem with a probable root cause.
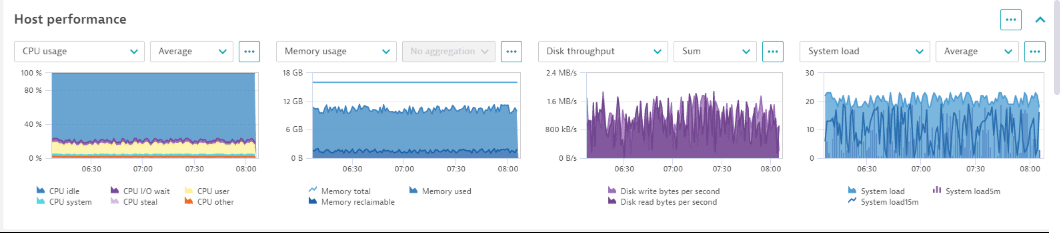
Our take: Automatic root-cause detection is the feature reviewers praise most. The trade-offs they report are cost at scale, licensing that is hard to budget, and a steep learning curve, with OneAgent feeling heavy on small or older hosts.
Pricing
Foundation & Discovery: $7/host/mo · Infrastructure Monitoring: $29/host/mo · Full-Stack Monitoring: $58/mo per 8 GiB host (adds APM, code profiling, Kubernetes). Billed hourly against an annual commitment. 15-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| OneAgent auto-discovers all processes and dependencies – no manual config | Most expensive at scale; DDU consumption hard to predict |
| Smartscape maps live relationships across the full topology | OneAgent Linux kernel module requires security team review |
| Davis AI reduces alert noise with single problem cards | Requires learning DDUs, Management Zones, Smartscape |
| Native OpenTelemetry ingestion alongside OneAgent | Overkill for simple uptime or resource monitoring |
6. AppDynamics: best for application server monitoring
AppDynamics (now sold as Splunk AppDynamics, part of Cisco) is an Application Performance Management (APM) platform that includes server and infrastructure monitoring alongside its core application visibility capabilities. It provides deep insight into application health, server resource utilization, transaction tracing, and code-level diagnostics, which in our view makes it well suited to environments where infrastructure health and application performance need to be analyzed together. Its Business Transaction monitoring ties server-side performance data directly to specific end-user application flows, and dynamic (baseline deviation) alerting reduces false positives compared to static threshold approaches. Auto-instrumenting agents cover Java, .NET, PHP, Node.js, and Python without code changes, and a C/C++ SDK supports native applications (Go SDK support ended in December 2024). It supports standard integrations with ITSM and alerting platforms.
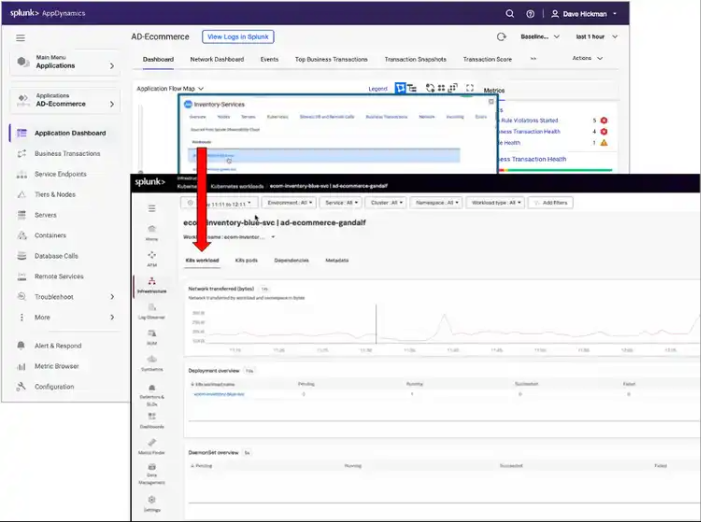
Our take: TrustRadius and Gartner reviewers highlight deep transaction tracing that connects technical problems to business impact. The common complaints are high licence and renewal costs for smaller teams, and dashboards that feel slow or dated.
Pricing
Billed annually, starting at: Infrastructure $6 · Premium $33 (adds APM and DB monitoring) · Enterprise $50 · SAP add-on $95 per CPU core/mo. RUM: $0.06/mo per 1,000 tokens. 15-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| Business Transaction monitoring ties server perf to user flows | Machine agents and APM agents licensed separately |
| Dynamic baseline alerting reduces false positives | Heavy resource footprint vs. lightweight agents |
| Deep Cisco networking and security integration | Significant expertise and onboarding time required |
| Auto-instrumenting agents for Java, .NET, PHP, Node.js, Python | Weaker standalone when APM is not in scope |
7. SolarWinds Server & Application Monitor: best for Windows server monitoring
SolarWinds Server & Application Monitor (SAM) is a commercial infrastructure monitoring product and a core component of the SolarWinds Observability Self-Hosted platform (formerly Hybrid Cloud Observability). It provides continuous server monitoring with support for both agent-based and agentless data collection, tracking response times, CPU load, memory, disk usage, and Windows event logs. Its built-in templates cover more than 1,200 applications (250+ out-of-the-box application monitor templates, with more shared on the THWACK community), including common server workloads such as IIS, SQL Server, Apache, and Active Directory. The AppStack dashboard correlates server health with application performance in a single view, and application dependency mapping provides visibility into cross-component relationships across hybrid IT environments. What we like for security-conscious teams is that the platform is self-hosted, on-premises or in your own cloud tenancy, so monitoring data stays in infrastructure you control.
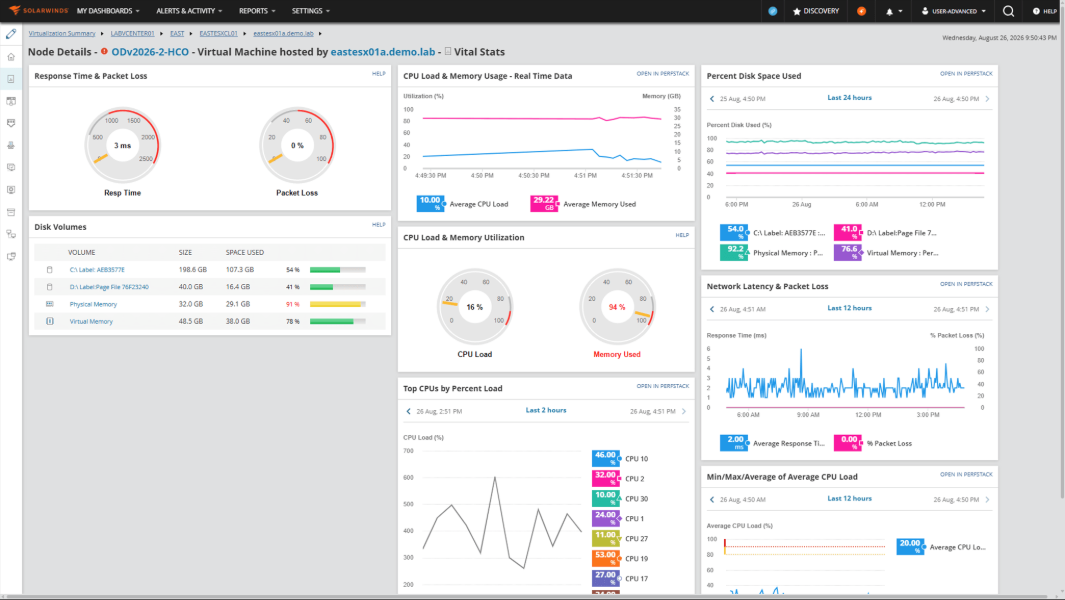
Our take: Reviewers like having servers, applications and dependencies in one console, which makes it faster to tell whether a problem sits in the server or the app. The recurring complaints are licensing that gets expensive as you grow, a resource-hungry platform, and a dated interface that needs careful alert tuning.
Pricing
Observability Self-Hosted from $8/node/mo (Essentials, which includes server and application monitoring), Advanced from $14/node/mo, Premier from $17.50/node/mo, billed annually on multi-year contracts. Database from $142/database/mo; ITSM from $39/technician/mo; Incident Response from $15/user/mo. 30-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| Templates covering 1,200+ applications (250+ out of the box) | Requires dedicated Windows Server for the Orion platform |
| AppStack correlates server health with application performance | Web interface dated vs. modern SaaS tools |
| Self-hosted, so data stays in infrastructure you control | Orion setup and tuning require significant time |
| WMI-based agentless monitoring for Windows | 2020 SUNBURST incident; some orgs apply extra scrutiny |
Note: SolarWinds also offers a number of free standalone utility tools (including a subnet calculator, TFTP server, and Solar-PuTTY), but these are network utilities, not server monitoring software.
8. Zabbix: best free, full-featured open-source platform
Zabbix is a mature open-source monitoring platform well known for its scalability and flexibility. It tracks server performance, availability, and network health in real time, providing detailed data on CPU usage, disk space, memory, and more. Zabbix supports multiple data collection methods, including its native Zabbix agent, agentless monitoring via SNMP, IPMI, and JMX, and checks over SSH and Telnet, which we found makes it adaptable to a wide range of environments and devices. Zabbix proxies enable distributed monitoring of remote or network-segmented locations from a central server, and its template system provides pre-configured monitoring for hundreds of common systems and applications, reducing initial setup time considerably. Zabbix supports a wide range of hardware and virtual environments, making it suitable for enterprises of all sizes.
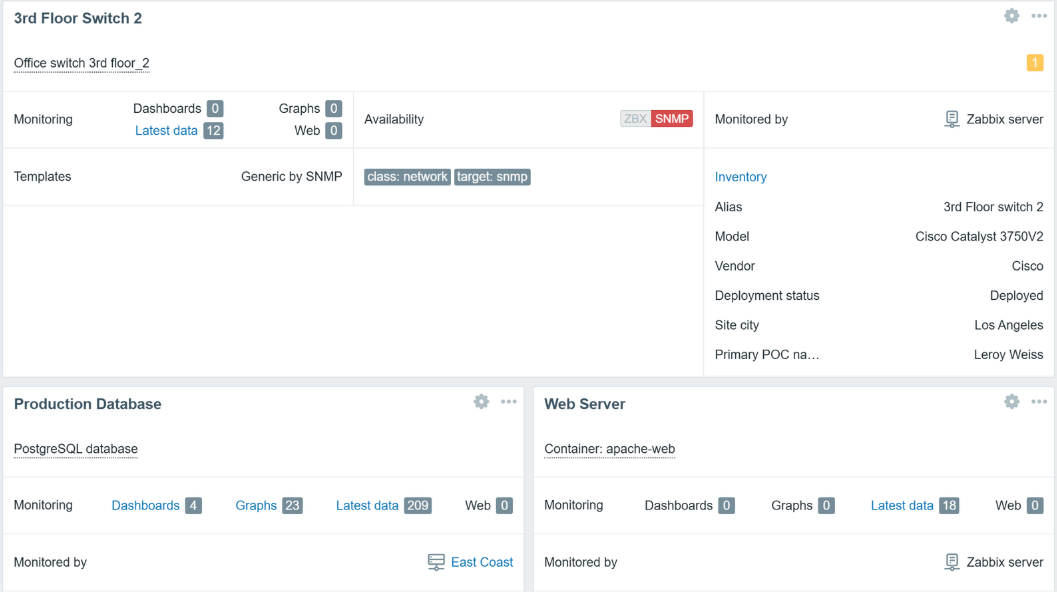
Our take: On G2 and Capterra, users value that Zabbix is free with no per-device licensing yet still covers servers, network gear and applications, with flexible triggers and fast alerts. The flip side, mentioned in almost every review, is a steep learning curve and a dated UI.
Pricing
Software is free and open source (AGPLv3 since version 7.0). Optional support subscriptions, billed annually: Silver €245/mo · Gold from €660/mo · Platinum/Enterprise/Global custom (USD pricing also available). Support is optional; the software runs fully without it (as of September 2026).
| Pros | Cons |
|---|---|
| Native agent, SNMP, IPMI, JMX, SSH, and Telnet collection | Web interface dated vs. SaaS alternatives |
| Proxy architecture for distributed/firewalled segments | Steep initial configuration curve |
| Template system for hundreds of systems out of the box | No built-in log management |
| No per-host or per-metric licensing cost at any scale | Primary support is community forums |
9. Prometheus: best for Kubernetes and cloud-native metrics
Prometheus is an open-source monitoring system and time series database that, in our experience, has become the de facto standard for metrics collection in cloud-native and Kubernetes environments. It is a graduated project of the Cloud Native Computing Foundation (CNCF), licensed under Apache 2.0.
Prometheus uses a pull-based model, scraping metrics at configured intervals from targets, either instrumented applications or exporters. For server-level metrics (CPU usage, memory, disk I/O, filesystem utilization, and network statistics), the standard exporters are node_exporter (for Linux and Unix systems) and windows_exporter (for Windows, maintained by the prometheus-community organization). Collected metrics are stored as time series and queried using PromQL, Prometheus’s purpose-built query language. Alerting is managed by Alertmanager, a separate component that handles routing, grouping, and deduplication of alerts to destinations such as PagerDuty, Slack, or email.
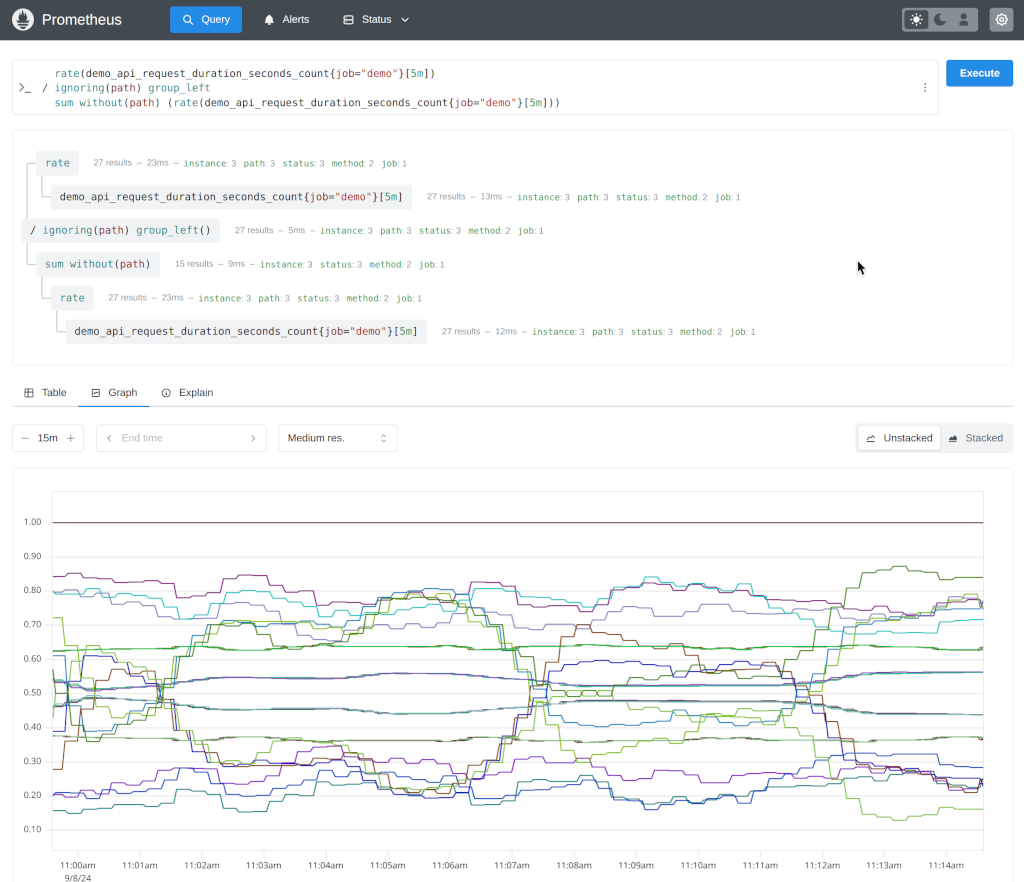
Our take: Users describe Prometheus as lightweight, free and a natural fit with Kubernetes and Grafana, with flexible alert routing. The consistent complaints are that PromQL is hard to learn and the built-in UI is basic, so almost everyone adds Grafana.
Pricing
Completely free and open source (Apache 2.0). No licensing fees, no commercial tiers; managed Prometheus-compatible services are sold separately by third parties (as of September 2026).
| Pros | Cons |
|---|---|
| De facto standard for Kubernetes; native k8s metrics API integration | Local TSDB defaults to 15-day retention; long-term needs a separate backend |
| remote_write to Thanos/Mimir/Cortex for multi-year retention | No built-in dashboard – requires Grafana |
| Federation supports hierarchical multi-cluster architectures | Pull model requires network access to all scrape targets |
| Hundreds of community exporters for databases, hardware, and cloud | High-cardinality label sets cause memory pressure |
10. Grafana Cloud: best for managed open-source observability
Grafana Cloud is a managed observability platform built on Grafana’s open-source stack. While Grafana itself is a visualization and dashboarding tool, Grafana Cloud adds managed data collection, storage, and alerting, which in our evaluation makes it a complete server monitoring solution when combined with its agent.
Server-side metric collection is handled by Grafana Alloy, an open-source, OpenTelemetry-compatible telemetry collector and the successor to Grafana Agent, which reached end of life in November 2025. Alloy collects Prometheus-compatible metrics, logs, traces, and profiles from monitored hosts and forwards them to Grafana Cloud’s backend services: Grafana Mimir for long-term metrics storage, Loki for log aggregation, Tempo for distributed traces, and Pyroscope for profiles. Alloy supports both pull-based (Prometheus-style scraping) and push-based (OTLP/OpenTelemetry) collection modes, giving it flexibility across different infrastructure patterns. For server monitoring specifically, deploying Alloy with its built-in system metric collection components gives you per-host visibility into CPU, memory, disk, and network usage, with pre-built dashboards available immediately in the Grafana Cloud interface. Grafana Alerting handles alert rule management across all data sources.
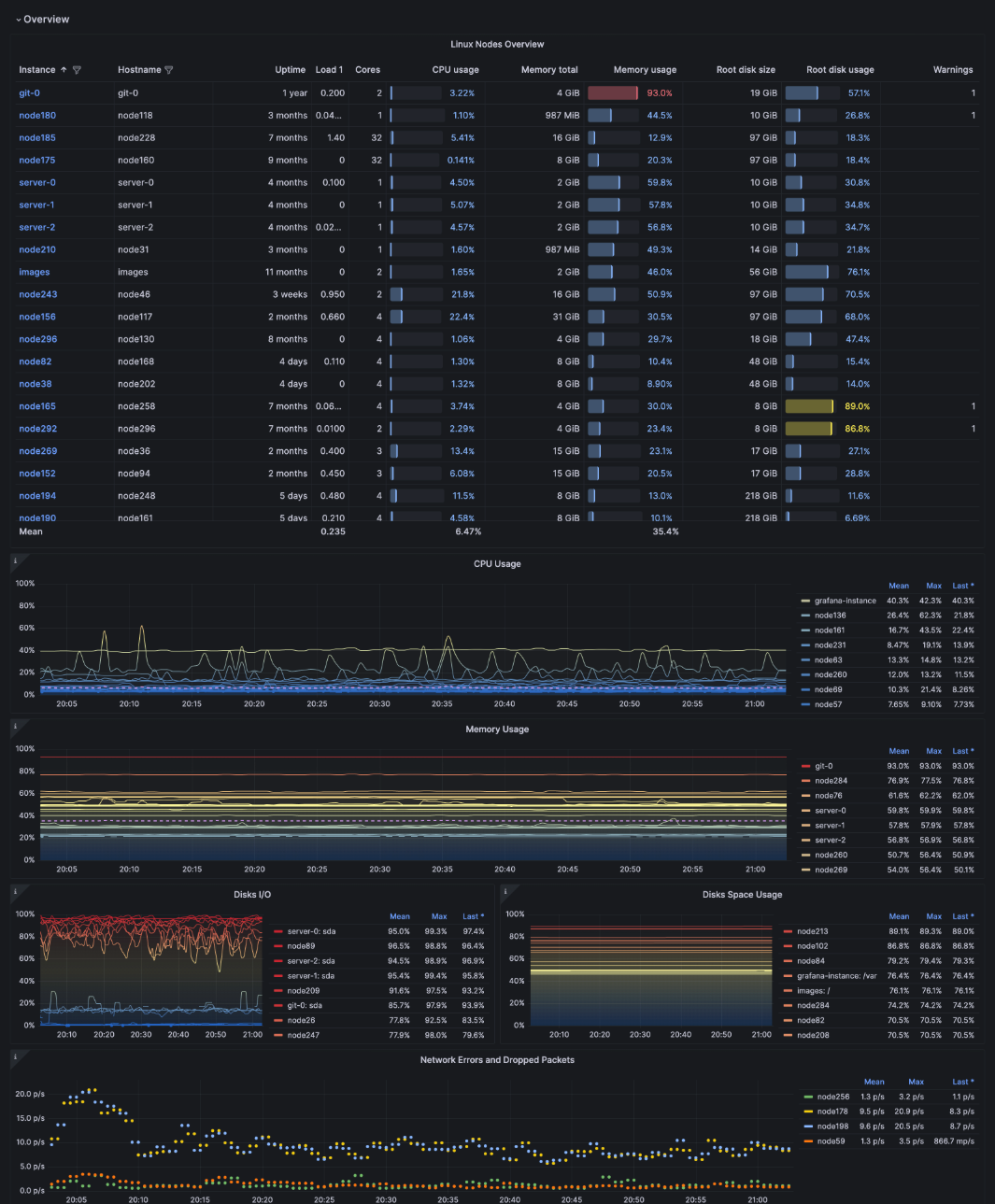
Our take: Gartner Peer Insights reviewers like correlating metrics, logs and traces in one interface on open standards, which reduces lock-in. The usual concern is usage-based cost that climbs quickly as data volume grows.
Pricing
Free: $0 always (14-day retention, community support). Pro: from $19/mo + usage (13-month metrics and 30-day logs/traces retention, 8×5 email support). Enterprise: from $25,000/year spend commitment (premium support, custom retention). Grafana OSS is AGPLv3; Alloy is Apache 2.0 (as of September 2026).
| Pros | Cons |
|---|---|
| Unified metrics, logs, traces, and profiles – no tool-switching | Grafana itself is not a collector; Alloy must be deployed separately |
| Alloy supports pull (Prometheus) and push (OTLP) collection modes | Free tier has series and retention limits |
| 300+ pre-built integration dashboards | Grafana OSS’s AGPL license needs legal review before embedding |
| Self-hosted OSS and Cloud share dashboard/alert definitions | Running Mimir + Loki + Tempo self-hosted is operationally complex |
11. New Relic: best free tier for full-stack observability
New Relic is a full-stack observability platform that provides deep visibility into server performance, application health, infrastructure metrics, and user experience data. The New Relic Infrastructure agent, separate from the APM agent, collects host-level metrics including CPU, memory, disk, network, and running process data independently of any application instrumentation. In our review, we found it offers rich visualization tools to help teams interpret performance data quickly, along with a broad integration ecosystem. AIOps alert correlation (Applied Intelligence) groups related alerts and suppresses notification noise across all monitored signals. New Relic’s unified user model supports fine-grained RBAC for sharing dashboards and alerts across teams.
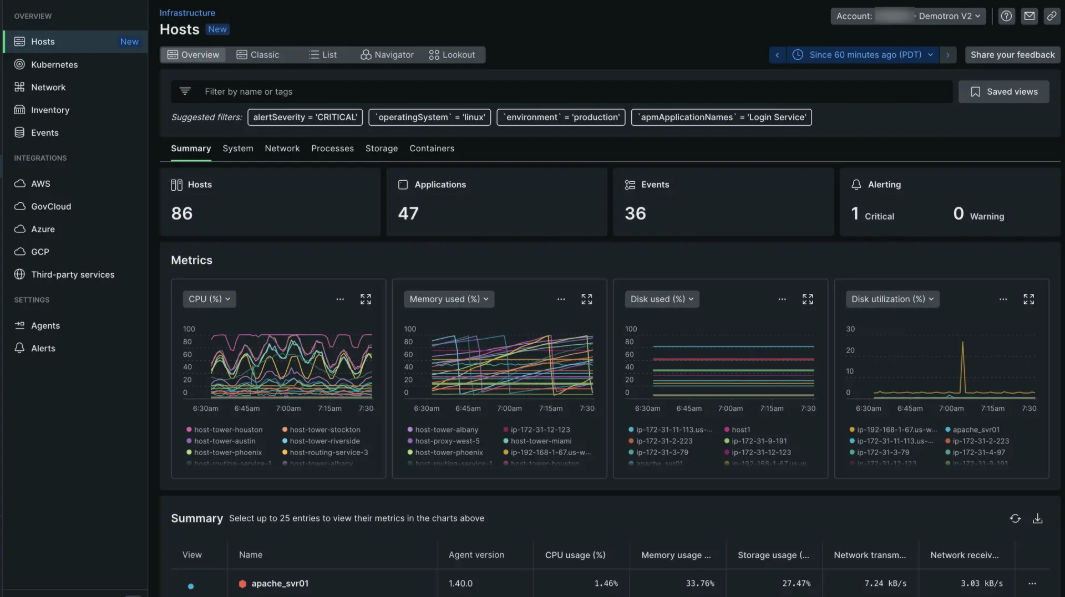
Our take: G2 reviewers point to one platform for APM, infrastructure, logs and traces, and a generous free tier that makes it easy to start. The common warning is that costs rise quickly as data ingest and full-user seats grow.
Pricing
Usage-based (users + data). Free: $0 forever (100 GB/mo ingest, 1 full platform user, no credit card). Standard: first full user $10, then $99/user/mo (max 5). Pro: $349/full user/mo billed annually ($418.80 pay-as-you-go), 2-hr SLA. Enterprise: custom (FedRAMP/HIPAA, 1-hr SLA). Core users $49/mo; data beyond 100 GB $0.40/GB ($0.60/GB Data Plus) (as of September 2026).
| Pros | Cons |
|---|---|
| Infrastructure agent collects host metrics independently of APM | Full-platform seats significantly more expensive than basic seats |
| AIOps correlates and deduplicates alerts across all signal types | Free tier data retention limited to 8 days |
| Fine-grained RBAC for cross-team dashboard and alert sharing | UI has been redesigned multiple times; older docs can be inconsistent |
| Vulnerability Management integrates security with infrastructure data | Higher CPU overhead vs. lightweight agents like Netdata |
12. LogicMonitor: best for hybrid enterprise IT
LogicMonitor is a cloud-based monitoring platform designed for hybrid infrastructure at scale. It tracks CPU load, memory usage, uptime, and other key performance metrics across on-premises and cloud environments from a unified dashboard. A key differentiator we noted is LogicMonitor’s automated device discovery and dynamic monitoring configuration, which significantly reduces manual setup in large environments. Monitoring is agentless: a lightweight LM Collector installed in each environment polls devices over SNMP, WMI, JMX, and REST APIs. Edwin AI, the AIOps layer on top of the LM Envision platform, provides event correlation, anomaly detection, and alert noise reduction. LogicMonitor completed its acquisition of Catchpoint in December 2025, adding internet and digital experience monitoring to the platform.
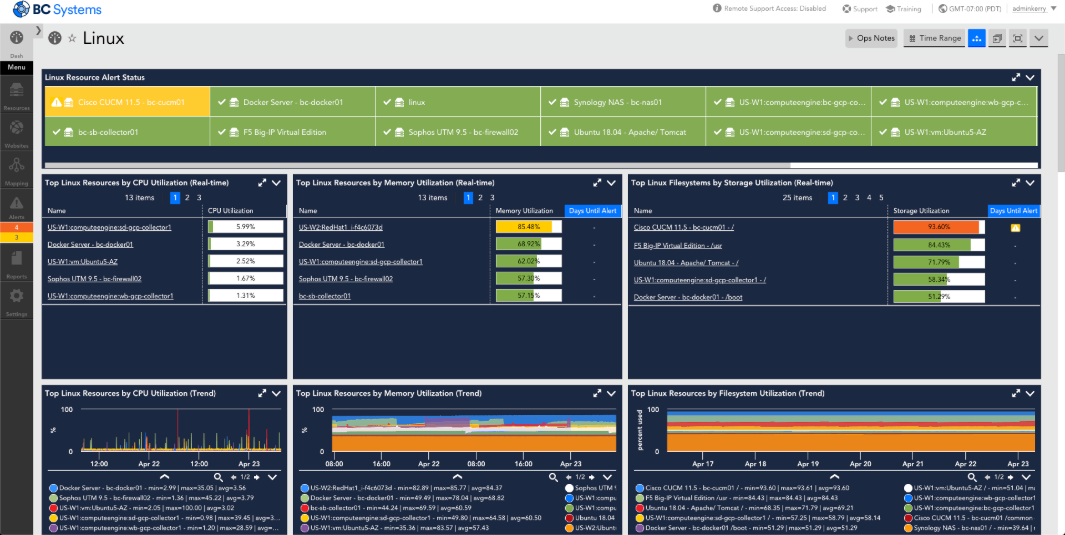
Our take: G2 reviewers like seeing on-prem, cloud and network in one console, and frequently single out fast rollout and knowledgeable support. The main complaints are cost for small teams or large device counts, and custom datasources that need scripting.
Pricing
Per hybrid unit/mo (list, starting): Essentials $16 · Advanced $27 · Signature + Edwin AI $53. Final price depends on volume and contract. 15-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| Automated device discovery reduces manual setup at scale | List prices public, but final cost set by sizing and contract |
| Edwin AI provides event correlation and anomaly detection | LM Collector runs on a dedicated host in your environment |
| Agentless collectors cover SNMP, WMI, JMX and REST | Less suited to Kubernetes-first teams vs. Prometheus or Datadog |
| Catchpoint acquisition adds digital experience monitoring | Customization requires LogicMonitor’s proprietary scripting |
13. ManageEngine OpManager: best for budget-conscious mid-size IT teams
ManageEngine OpManager, in our review, provides comprehensive monitoring for both physical and virtual servers. It tracks CPU usage, memory, disk space, and event logs, and supports proactive alerting to help prevent downtime. OpManager supports SNMP v1, v2c, and v3 for agentless monitoring of network devices alongside optional server agents, and includes built-in network topology maps that visualize device relationships and aid in impact analysis during incidents. Business hours-aware alerting allows teams to suppress notifications outside on-call windows. OpManager covers URL monitoring, Windows event logs, Microsoft Exchange servers, and VMware ESX/ESXi environments. The OpManager Plus edition extends the base product with network configuration management (NCM) and storage monitoring under a single license.
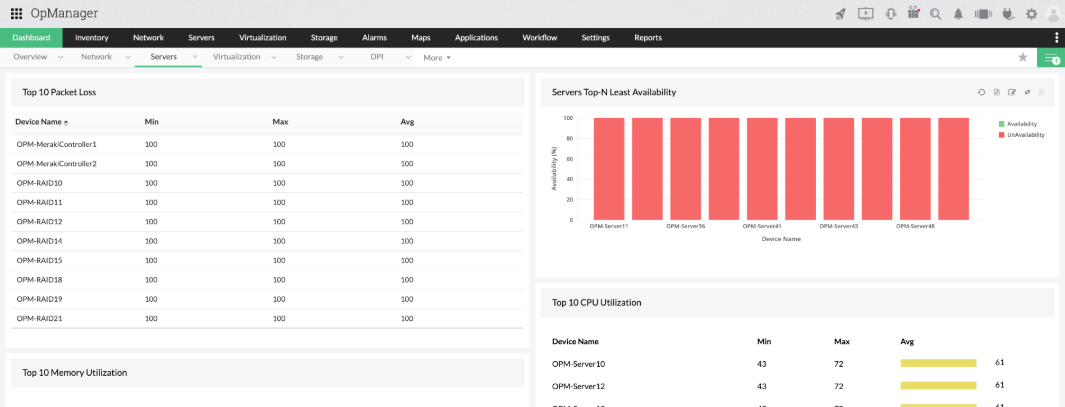
Our take: Value for money is the most repeated praise on Capterra, with reviewers saying it costs noticeably less than PRTG or SolarWinds for similar coverage and is quick to deploy. The complaints: a dated, cluttered interface, and alert floods until thresholds are tuned.
Pricing
Annual subscription: Standard from $95 (10 devices) · Professional 10 devices $145 · 50 $645 · 100 $1,145 · 500 $3,845 · Enterprise from $4,595 (250 devices). Perpetual licenses also sold (plus 20% AMS). Free edition (3 devices), 30-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| Built-in network topology maps aid incident impact analysis | Dense UI can overwhelm new users |
| SNMP v1/v2c/v3 agentless alongside server agents | Cloud infra monitoring (AWS/Azure/GCP) requires OpManager Plus |
| Business hours-aware alerting suppresses off-hours noise | Mobile app limited vs. web console |
| OpManager Plus adds NCM and storage monitoring under one license | Support quality inconsistent across regions |
14. PRTG Network Monitor: best for SMB server and network monitoring
PRTG Network Monitor is an all-in-one monitoring solution for small to mid-size server and network environments, with PRTG Enterprise Monitor available for larger estates. It tracks real-time server availability, performance metrics, and network traffic, offering detailed insights into IT infrastructure health. As we noted in our review, its sensor library covers SNMP, WMI, NetFlow/sFlow/IPFIX traffic analysis, REST API endpoints, and custom scripts within a single product. PRTG Hosted Monitor provides a cloud-managed deployment option for teams that prefer not to self-host, and a map designer allows building custom infrastructure topology views with drag-and-drop. PRTG uses a sensor-based licensing model: cost scales with the number of sensors deployed, where each monitored value (such as CPU load or one port’s traffic) uses one sensor.
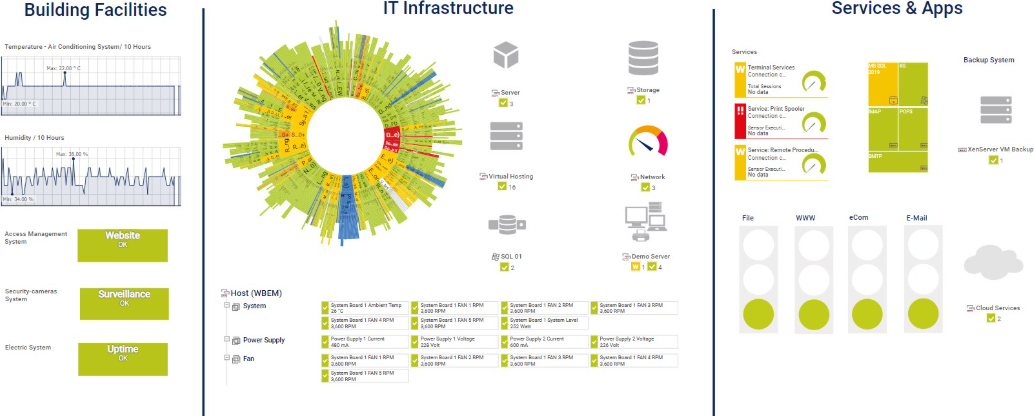
Our take: Capterra reviewers praise easy setup with auto-discovery that adds devices and sensors almost on its own, and a useful 100-sensor free version. The complaints we saw most: costs that climb as sensor counts grow, and a dated, Windows-only core server.
Pricing
Subscription (per mo, paid annually): PRTG 500 (~50 devices) $200 · PRTG 1000 (~100) $358 · PRTG 2500 (~250) $742 · PRTG 5000 (~500) $1,300 · PRTG 10000 (~1,000) $1,642. Over 1,000 devices: PRTG Enterprise Monitor by quote. Free version up to 100 sensors, 30-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| Sensor library: SNMP, WMI, flow analysis, REST APIs, custom scripts | Core self-hosted product runs on Windows Server only |
| PRTG Hosted Monitor provides a cloud-managed option | Sensor-based cost estimation complex as environments grow |
| Map designer enables custom topology views | UI not modernized; dated vs. SaaS alternatives |
| Five tiered plans ($200–$1,642/mo) match budget to scale | Distributed monitoring via remote probes needs additional Windows infra |
15. Uptime Kuma: best for simple self-hosted uptime and status pages
Uptime Kuma is a free, open-source, self-hosted uptime monitoring tool released under the MIT license, and it is new to this list in our September 2026 review. It runs as a Node.js application and is most often deployed with a single Docker command, storing data in SQLite by default or MariaDB since version 2.0. Monitor types include HTTP(S), HTTP(S) keyword and JSON query, TCP port, ping, DNS record, push (heartbeat), Docker container, Steam game server and, since version 2.5, NTP. Alerts can be sent through more than 90 notification services, including email, Slack, Discord, Telegram and webhooks. It also lets you publish multiple public status pages with custom domains, and shows TLS certificate information. The latest stable release is 2.5.5 (September 2026).
To be clear about scope: Uptime Kuma checks whether services are reachable and responsive. It does not collect host CPU, memory or disk metrics, so it complements a metrics tool rather than replacing one. Because checks run from wherever you host it, it also can’t tell you how your server responds for users in other regions.
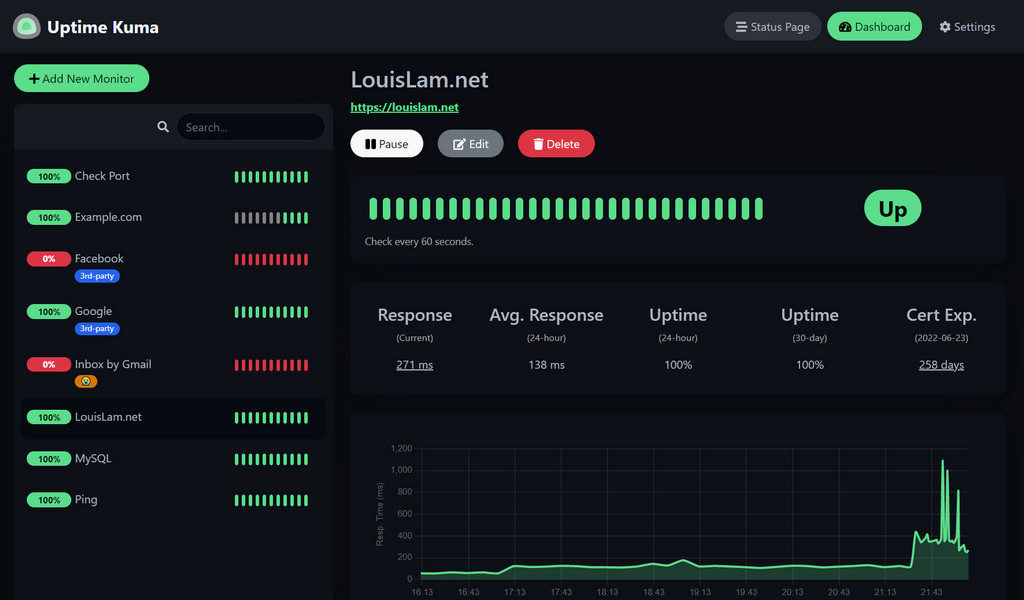
Our take: Reviewers and self-hosting communities love its clean dashboard, one-command Docker setup and wide choice of notification channels. The recurring limitations are monitoring from a single location, which is also a single point of failure, and GUI-only configuration with no official REST API.
Pricing
Completely free and open source (MIT license), with no paid tiers or official managed/SaaS version; you host and maintain it yourself (as of September 2026).
| Pros | Cons |
|---|---|
| Free MIT license, no monitor limits | Checks run from one location – your own server |
| One Docker command gets it running | If its host goes down, monitoring goes with it |
| 90+ notification services built in | No host CPU/memory/disk metrics |
| Multiple status pages with custom domains | No official REST API or managed hosting |
16. Elastic Observability: best for unifying logs, metrics and traces
Elastic Observability is the infrastructure and application monitoring layer of the Elastic Stack. Server metrics are collected by the Elastic Agent, the unified agent Elastic recommends over the older individual Beats shippers, using the System integration, which captures CPU usage, memory, disk I/O, network statistics, and running process metrics from the host. Collected data is shipped to Elasticsearch for storage and surfaced for visualization and alerting through Kibana. Fleet provides centralized management for deploying, updating, and configuring Elastic Agents across all monitored hosts from the Kibana interface, without requiring manual per-host operations. On Platinum and higher tiers, Kibana’s ML-based anomaly detection jobs can automatically identify unusual patterns in server metric time series. What we value most is that the unified Elastic Stack means metrics, logs, APM traces, and synthetic monitoring data all live in the same Elasticsearch cluster, eliminating cross-tool correlation.
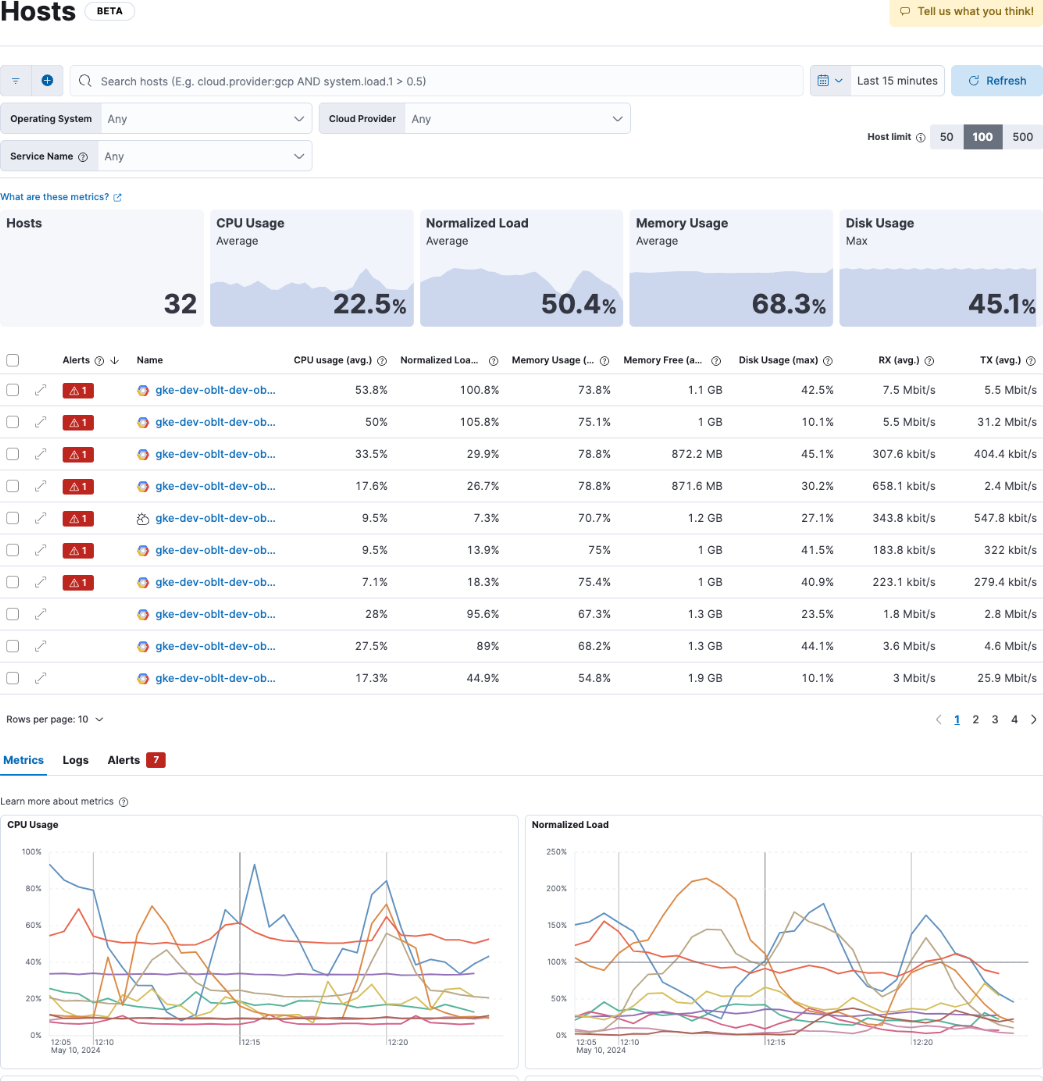
Our take: Gartner and G2 reviewers praise how much data Elastic can ingest and how fast its search is, with flexible Kibana dashboards. The consistent complaints are a steep learning curve, and costs and resource use that grow fast with data volume.
Pricing
Elastic Cloud Hosted: Standard from $99/mo · Gold from $114/mo · Platinum from $131/mo (adds ML anomaly detection) · Enterprise from $184/mo. Serverless usage-based option also available. 14-day free trial. Self-managed Basic: free (as of September 2026).
| Pros | Cons |
|---|---|
| Fleet enables centralized Elastic Agent management from Kibana | Elasticsearch cluster management complex and resource-intensive |
| ML anomaly detection (Platinum+) flags unusual server metrics | Elastic License 2.0 – not OSI open source |
| Unified cluster for metrics, logs, APM, and synthetics | Ingest costs unpredictable with high-cardinality metrics |
| Full-text search across all ingested data including log metadata | Steep learning curve; requires Elasticsearch and Kibana expertise |
17. Icinga: best for config-as-code Linux teams
Icinga began as an open-source fork of Nagios in 2009, but Icinga 2, released in 2014, was a complete rewrite in C++ with an entirely new architecture, configuration language (the Icinga DSL), and feature set. It is today a fully independent monitoring platform developed and maintained by Icinga GmbH. It monitors server and network availability and tracks metrics including CPU, memory, disk, and network health, with instant alerting when issues are detected. Icinga also supports hardware monitoring (switches, routers) as well as HTTPS and SMTP status checks. We particularly like that Icinga Director provides a web-based GUI for managing monitoring configuration without editing DSL files by hand. Icinga DB replaces the older IDO (Icinga Data Output) backend with a high-performance Redis + MySQL/PostgreSQL architecture for improved query performance. The Icinga DSL enables monitoring configuration to be version-controlled and deployed via CI/CD pipelines. Icinga for Windows is a PowerShell-based framework for deep Windows server monitoring, covering services, event logs, and performance counters.
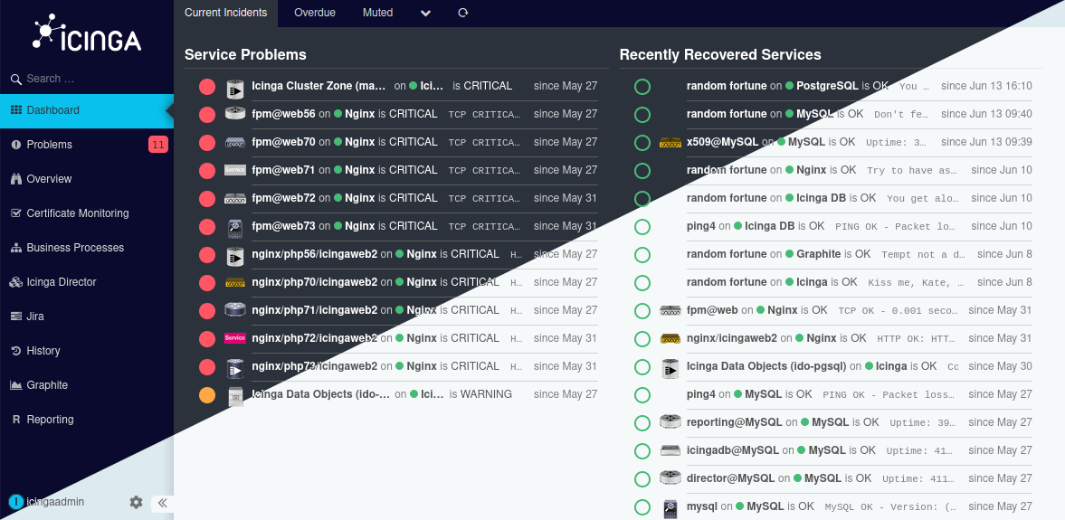
Our take: Capterra reviewers describe Icinga as very flexible and cost-effective compared with commercial tools. Nearly every review also mentions demanding initial setup that needs Linux and configuration expertise.
Pricing
Software free (GPLv2). Optional annual subscriptions (USD): Repository $5,000 (60-day trial) · Modules $2,000 · Basic Support $15,000 (8×5, 2 servers, +$2,000 per extra server) · Premium Support $30,000 (8×5, 5 servers) · Enterprise Support from $60,000 (24×7, 10 servers, by quote) (as of September 2026).
| Pros | Cons |
|---|---|
| Icinga Director – web GUI; no DSL file editing for day-to-day ops | Multiple components (2, Web, DB, Director) must be maintained separately |
| Icinga DB: high-performance Redis + MySQL/PostgreSQL backend | Steep initial configuration; Icinga DSL requires learning |
| DSL is version-controllable and CI/CD-deployable | Limited built-in dashboarding; Grafana typically added |
| Icinga for Windows: deep server monitoring incl. event logs | Commercial support requires a paid contract |
18. Nagios: best for plugin-driven on-prem monitoring
In our experience, Nagios is one of the most widely used open-source monitoring tools, known for its flexibility and extensive plugin ecosystem. It is available in two distinct editions: Nagios Core, which is free and open source with no node limits, and Nagios XI, a commercial product with a paid license that adds a web-based configuration UI, reporting dashboards, and enterprise support. Nagios Core monitors server availability, disk space, memory, CPU usage, and more via its community-maintained plugin library. NRPE (Nagios Remote Plugin Executor) lets the Nagios server run checks on remote hosts over an encrypted connection; because the server initiates the connection, the monitored host must allow inbound TCP 5666 from it. NSCA (Nagios Service Check Acceptor) supports passive checks, where monitored hosts push check results to the Nagios server, which makes it the better fit for firewalled or isolated environments. Nagios Core’s entirely file-based configuration makes it fully manageable via infrastructure-as-code tools such as Ansible, Puppet, and Chef.
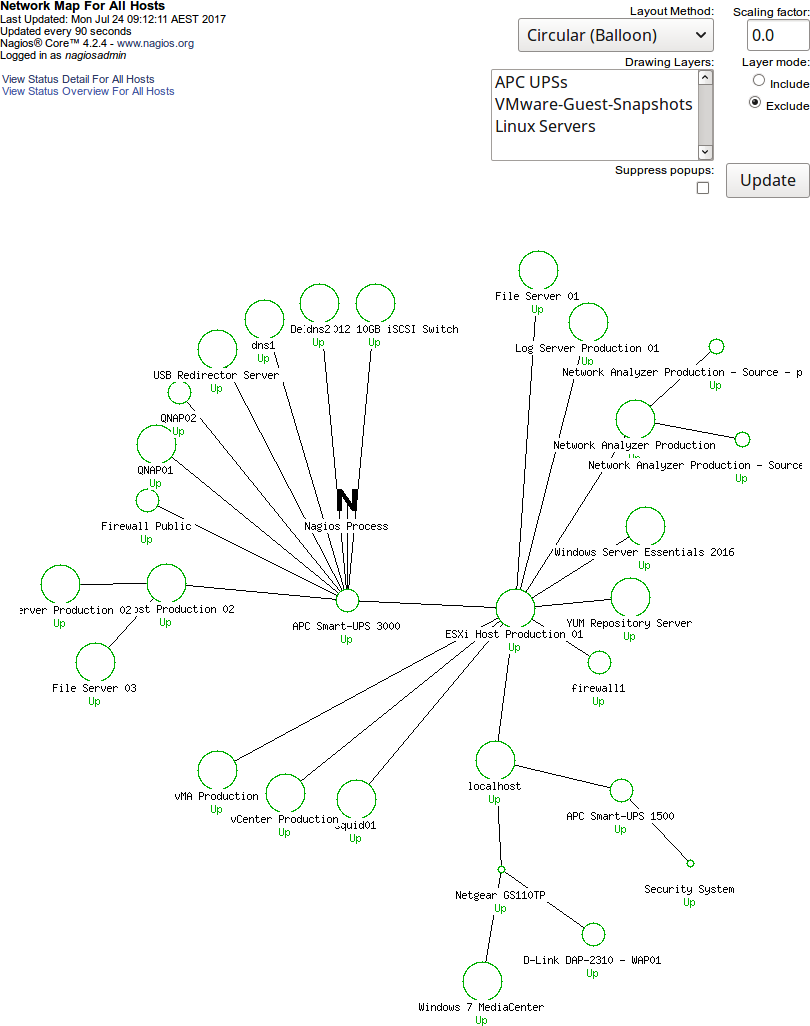
Our take: Capterra reviewers value the huge plugin ecosystem and how easy it is to write custom checks. The trade-offs they report are a dated web UI, and setup and tuning that take real time and Linux skills.
Pricing
Nagios Core: free. Nagios XI (perpetual license + annual renewal): Free Edition $0 (7 nodes or 100 services) · 100-Node $2,595 + $2,104/yr · 200-Node $4,395 + $3,466/yr · 300-Node $6,195 + $4,955/yr · 500-Node $8,295 + $6,939/yr · 1,000-Node $14,995 + $11,898/yr · 2,000+ nodes: contact sales. Enterprise edition: +$2,095 upfront + $1,066/yr. 30-day free trial (as of September 2026).
| Pros | Cons |
|---|---|
| NRPE: encrypted remote checks (host allows inbound TCP 5666) | Nagios Core has no web configuration UI – flat text files only |
| NSCA: firewalled hosts push check results to the server | Core web interface minimal; visualization needs third-party tools |
| File-based config fully manageable via Ansible/Puppet/Chef | Synchronous check execution limits scalability without tuning |
| Decades of community plugins cover virtually every system | Nagios XI cost hard to justify vs. Icinga or Checkmk |
19. Pandora FMS: best for budget hybrid IT and MSPs
Pandora Flexible Monitoring System (FMS) is a comprehensive monitoring solution that supports hybrid IT environments covering physical, virtual, and cloud servers from a single dashboard. We found its highly customizable platform tracks real-time metrics including CPU usage, memory, disk space, and network performance. Pandora FMS supports both agent-based and agentless monitoring, including SNMP, WMI, and SSH-based checks, from the same installation. An event correlation engine links related alerts across multiple monitored devices to reduce noise, and a built-in visual console provides topology and status overviews without requiring a third-party visualization tool.
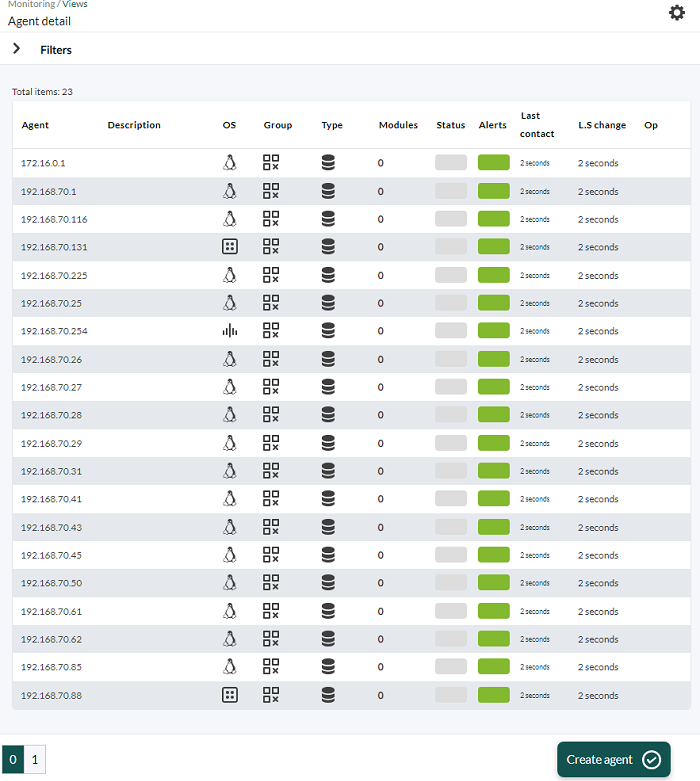
Our take: Capterra reviewers rate Pandora FMS highly for customization and value, including a capable free community edition. The common complaints are a steep learning curve, demanding initial setup and some documentation that refers to older versions.
Pricing
Per-device model. Free (Open Source): €0 on-prem (up to 50 agents). ONE: from €2,447/yr (100+ devices). NMS: from €1,590/yr (100+ network devices). RMM: from €612/yr (100+ workstations). MSP: from €0.51/agent/mo (100+ agents). MaaS (SaaS): from €783/mo (300+ agents). Corporate: custom (1,000+ devices, on-prem or SaaS). Free trial available (as of September 2026).
| Pros | Cons |
|---|---|
| Agent + agentless (SNMP, WMI, SSH) from a single install | Community edition limited in scale and features vs. Enterprise |
| Event correlation reduces cross-device alert noise | English documentation less comprehensive than Spanish |
| Built-in visual console – no third-party viz tool needed | Complex setup; significant initial investment required |
| Open-source community edition at no license cost | Smaller global ecosystem than Zabbix, Nagios, or Prometheus |
20. Checkmk: best for Linux fleets with auto-discovery
Checkmk is a server monitoring platform known for its scalability and large plugin ecosystem. It provides real-time monitoring for server metrics including CPU usage, disk space, and memory, with a robust alerting system that notifies teams of issues as they arise. A standout capability we noted is Checkmk’s auto-discovery, which automatically detects and configures monitoring for all services on a newly added host, significantly reducing manual check configuration. The Checkmk agent (check_mk_agent) is available for Linux, Windows, Unix variants such as AIX, Solaris and FreeBSD, and more; SNMP monitoring covers network devices and agentless targets. In commercial editions, the agent bakery allows auto-generating pre-configured agent packages for one-click deployment across large fleets.
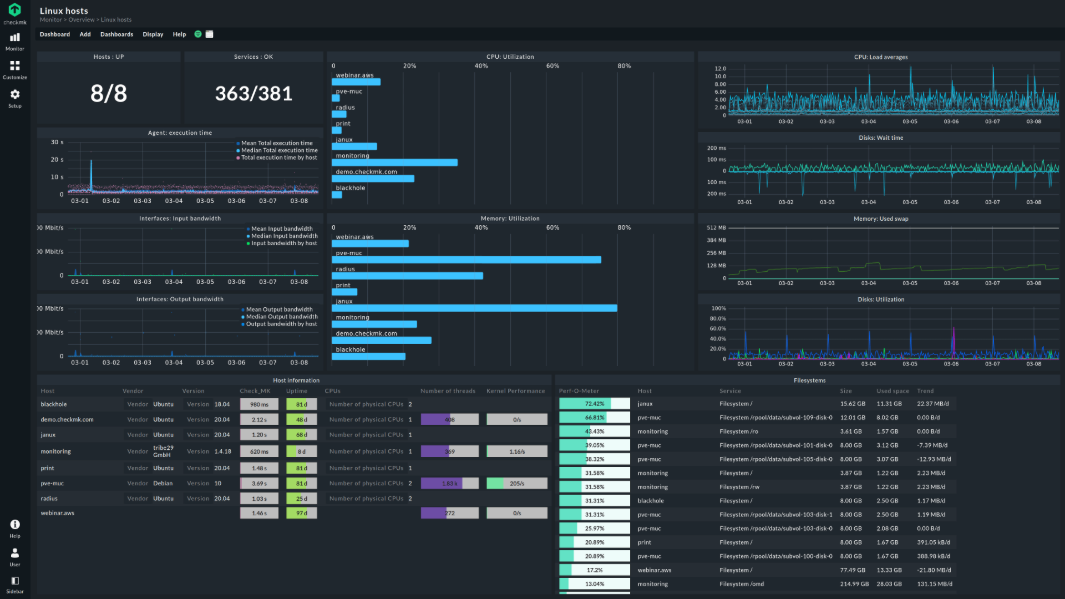
Our take: G2 and Capterra reviewers say Checkmk scales well from small setups to very large host counts, and that rule-based configuration plus auto-discovery saves setup time. The trade-off is a learning curve driven by the sheer number of rules and options.
Pricing
Community: free forever (~100 hosts, 2,000+ integrations). Pro: from €190/mo billed annually (~€1.90/host). Ultimate: from €275/mo billed annually (~€2.75/host). Cloud (SaaS): from €240/mo (~€2,880/yr). 30-day full-featured free trial (as of September 2026).
| Pros | Cons |
|---|---|
| Auto-discovery configures monitoring for all services on new hosts | Community Edition lacks agent bakery and advanced reporting |
| Agent bakery auto-generates pre-configured packages for fleet deployment | Rulesets and WATO/Setup require Checkmk-specific learning |
| Four editions from free to fully managed SaaS | Distributed multi-site monitoring adds operational complexity |
| Agent + SNMP covers both agent-based and agentless targets | Less native Kubernetes depth vs. Prometheus or Datadog |
21. Sensu Go: best for event-driven DevOps pipelines
Sensu Go is an open-source, event-driven monitoring framework built for modern infrastructure and DevOps workflows. It is the current generation of the Sensu platform, rewritten entirely in Go from the original Ruby-based Sensu Core, with an embedded etcd backend for distributed state management. Sensu operates on an agent model: the sensu-agent runs on each monitored server and executes scheduled checks, including CPU, memory, disk, and network health checks from community plugins published as assets on Bonsai, or from the curated Sensu Catalog in commercial editions. Check results are forwarded to the Sensu backend, which processes them through a configurable pipeline of filters, mutators, and handlers to trigger alerts, route events to PagerDuty or Slack, or push metrics downstream to time series databases such as InfluxDB or Prometheus. Dynamic runtime assets allow check scripts and their dependencies to be distributed to agents automatically at runtime, without requiring manual installation on each host, which we see as a significant operational advantage in large or frequently changing environments. The Sensu backend supports clustering for high availability.
One caution from our review: Sensu has been owned by Sumo Logic since 2021, and the most recent releases we could confirm date from 2023. Check the project’s current release activity before you standardize on it.
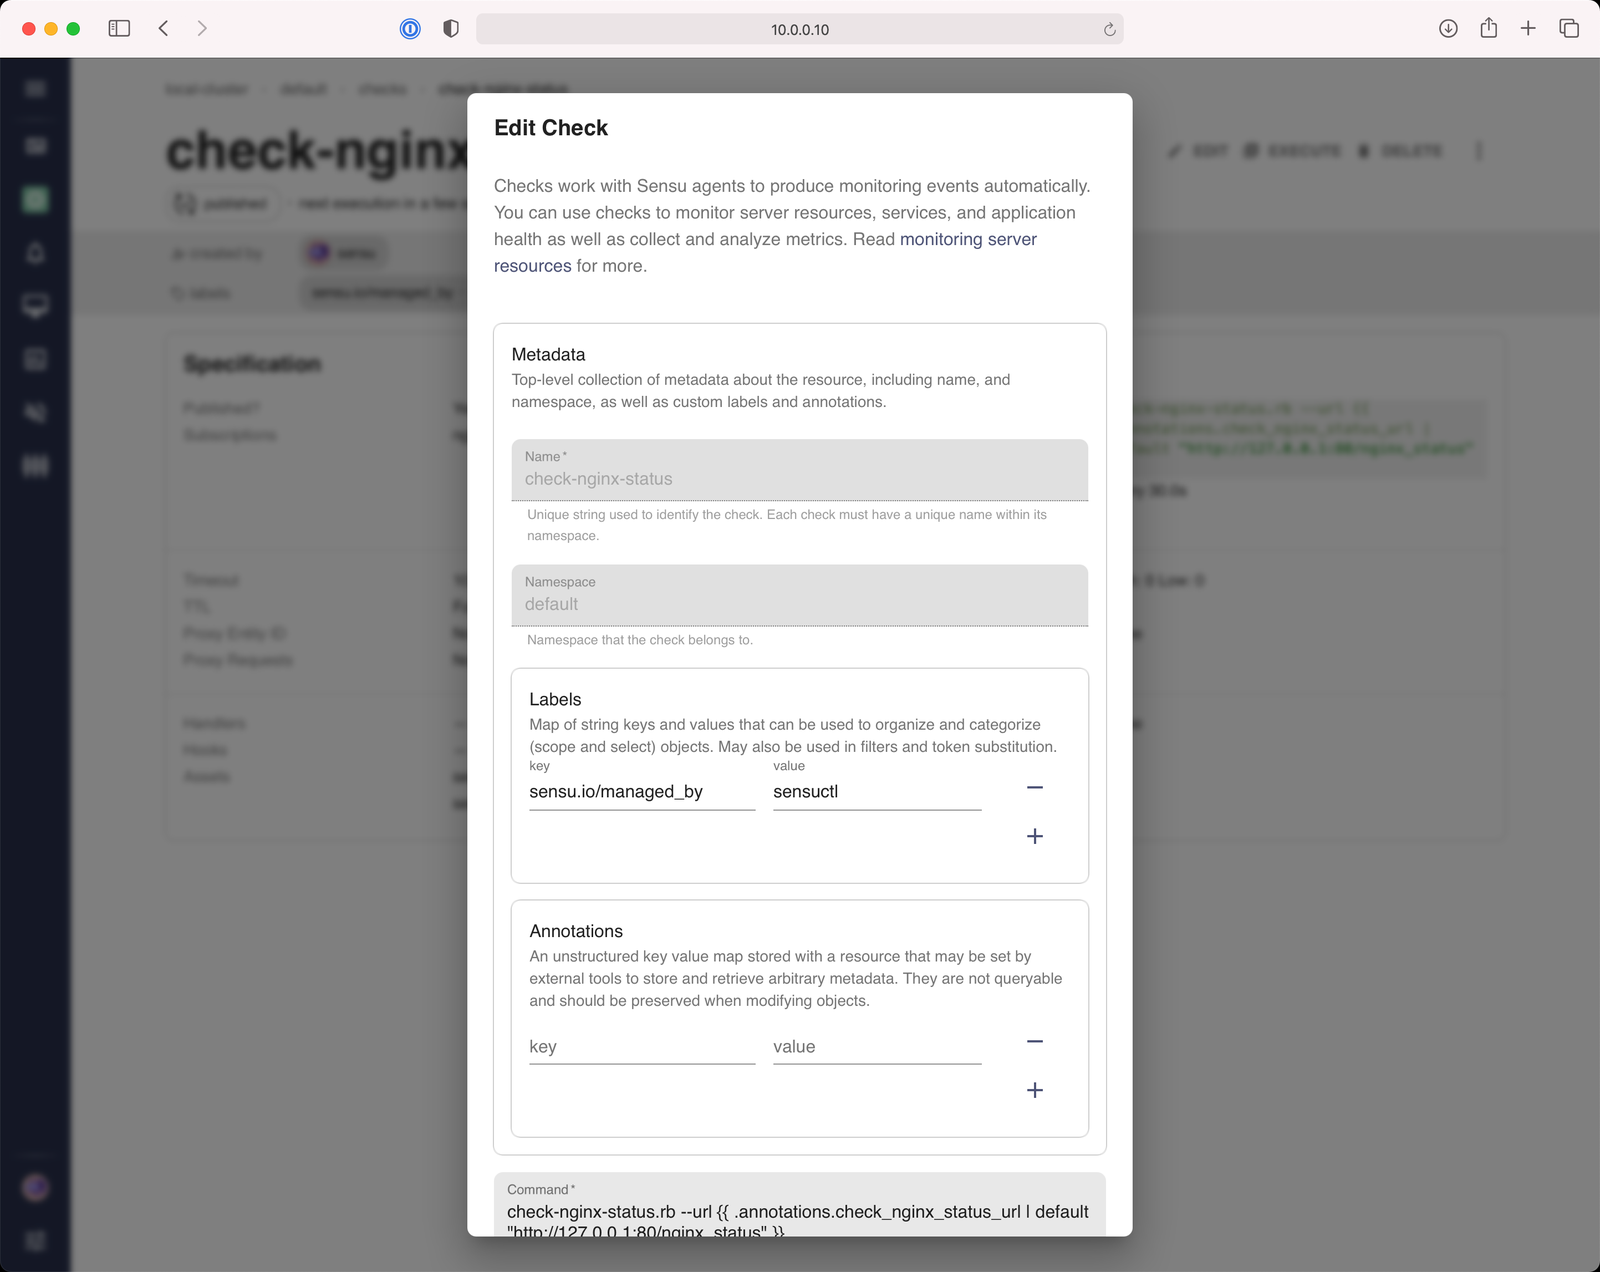
Our take: Reviewers like Sensu’s flexible event pipeline and smooth routing to tools like Slack and PagerDuty. The complaints are a sparse dashboard and thin beginner documentation, and the review base itself is small and mostly from 2023 or earlier.
Pricing
Per node/mo: Free $0 (≤100 nodes, no support). Pro $3/node billed annually (min 100 nodes, max 3,000, 6-hr SLA). Enterprise $5/node billed annually (min 300 nodes, unlimited, 3-hr SLA). 14-day trial for Pro/Enterprise (as of September 2026).
| Pros | Cons |
|---|---|
| Configurable pipeline (check→filter→mutator→handler) for granular routing | Smaller community and plugin library than Nagios or Prometheus |
| First-class support for ephemeral and auto-scaling infrastructure | HA clustering requires etcd operational knowledge |
| Built-in HA backend clustering without a separate load balancer | No built-in visualization – Grafana or Kibana required |
| IaC-friendly: config fully manageable via API with Ansible/Puppet/Chef | Pro requires ≥100 nodes; Enterprise requires ≥300 nodes minimum |
22. WhatsUp Gold: best for visual network and server mapping
WhatsUp Gold, developed by Progress Software, is an IT infrastructure management solution that provides visibility into key performance metrics including CPU usage, disk space, memory, and network traffic. One feature we noted is its automatic network topology discovery, which maps device relationships and dependencies, enabling faster impact analysis during outages. Dependency-aware alerting suppresses downstream alerts when an upstream root-cause device is already in an alert state, reducing notification noise in interconnected environments. SNMP-based monitoring provides agentless coverage of network devices, servers, and storage within a single product, and built-in Layer 2/3 discovery maps devices down to port-level connectivity. Customizable dashboards deliver real-time server health views.
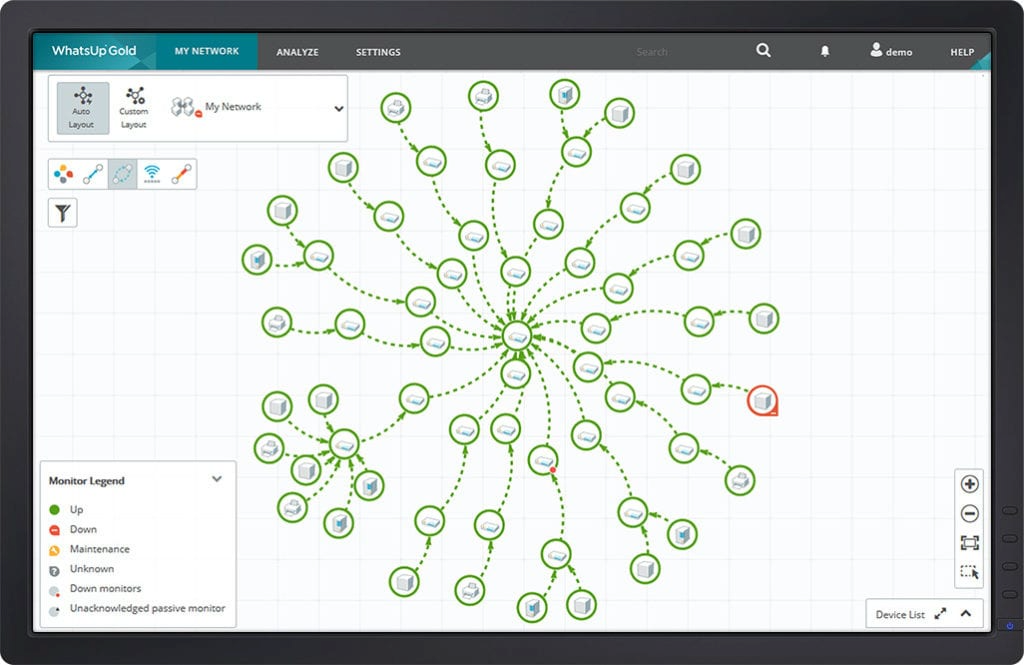
Our take: Capterra reviewers find WhatsUp Gold easy to deploy, with clear dashboards and maps, and good value next to heavier suites. The complaints: dashboards that slow down at very large device counts, and reporting and alert setup that feel fiddly.
Pricing
Annual pricing (from 50 devices): Business from $1,229/yr · Enterprise from $2,049/yr · Enterprise Plus from $3,469/yr · Enterprise Scale: custom (up to 25,000 devices per instance). Free Edition: up to 10 devices at no cost. Free trial available (as of September 2026).
| Pros | Cons |
|---|---|
| Auto network topology discovery maps device relationships | Primarily network-focused; process-level/log depth is shallow |
| Dependency-aware alerting suppresses downstream noise | Windows Server–only install; no SaaS or Linux-native option |
| SNMP agentless covers servers, network devices, and storage | Device-based pricing makes SaaS cost comparisons difficult |
| Built-in Layer 2/3 discovery down to port level | Limited Kubernetes and container support |
23. LibreNMS: best free SNMP-based monitoring
LibreNMS is an open-source network and server monitoring tool that provides near real-time visibility into server health, including CPU usage, memory, and disk space. Its SNMP-based autodiscovery automatically adds devices and begins collecting metrics with minimal manual configuration. The alerting engine supports complex multi-condition alert rules with multiple notification transports including email, Slack, and PagerDuty. Built-in syslog and SNMP trap reception consolidates log and event data alongside performance metrics in a single interface. It supports a broad range of hardware and operating systems, making it well suited to large and diverse IT environments. We found its open-source foundation allows for extensive customization, making it a popular choice for organizations with complex or non-standard monitoring needs.
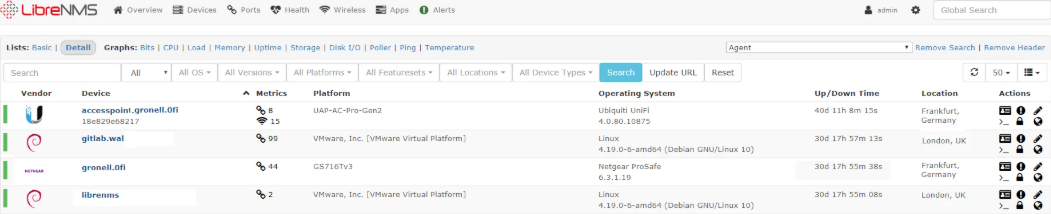
Our take: G2 reviewers rate LibreNMS as easy to install for an open-source NMS, with broad automatic discovery and flexible alert rules at zero cost. The limitations they raise are a web UI that slows down as device counts grow into the hundreds, and no official commercial support.
Pricing
Completely free and open source (GNU GPL v3). No licensing fees and no device limits. Third-party add-ons, such as a WHMCS billing module, are sold separately by other vendors (as of September 2026).
| Pros | Cons |
|---|---|
| SNMP autodiscovery adds devices and begins collecting metrics automatically | Monitoring depth relies on SNMP; process-level metrics need extensions or scripts |
| Alert engine: complex multi-condition rules, multiple transports | Web UI functional but not as polished as commercial tools |
| Built-in syslog and SNMP trap reception alongside performance metrics | Requires Linux host with PHP, MySQL/MariaDB, and RRDtool |
| Active open-source community with regular releases | No native container or Kubernetes monitoring |
24. Netdata: best for real-time server monitoring
Netdata provides real-time, per-second performance monitoring for servers, containers, and applications. Its lightweight agent is designed for low resource overhead (Netdata’s documentation cites 1% to 5% of a single CPU core at default settings), making it practical for large-scale deployments. Unusually among the monitoring tools we reviewed, Netdata stores metrics locally on the agent by default, meaning no central database is required for basic single-host monitoring. Netdata Parents enable a streaming and replication architecture where child agents forward metrics to a central parent node for aggregation and longer retention without an additional time series database. On-agent ML-based anomaly detection runs locally and identifies unusual patterns without sending data to an external service. Netdata’s customizable dashboards and alerting system make it straightforward to monitor and act on performance issues as they occur.
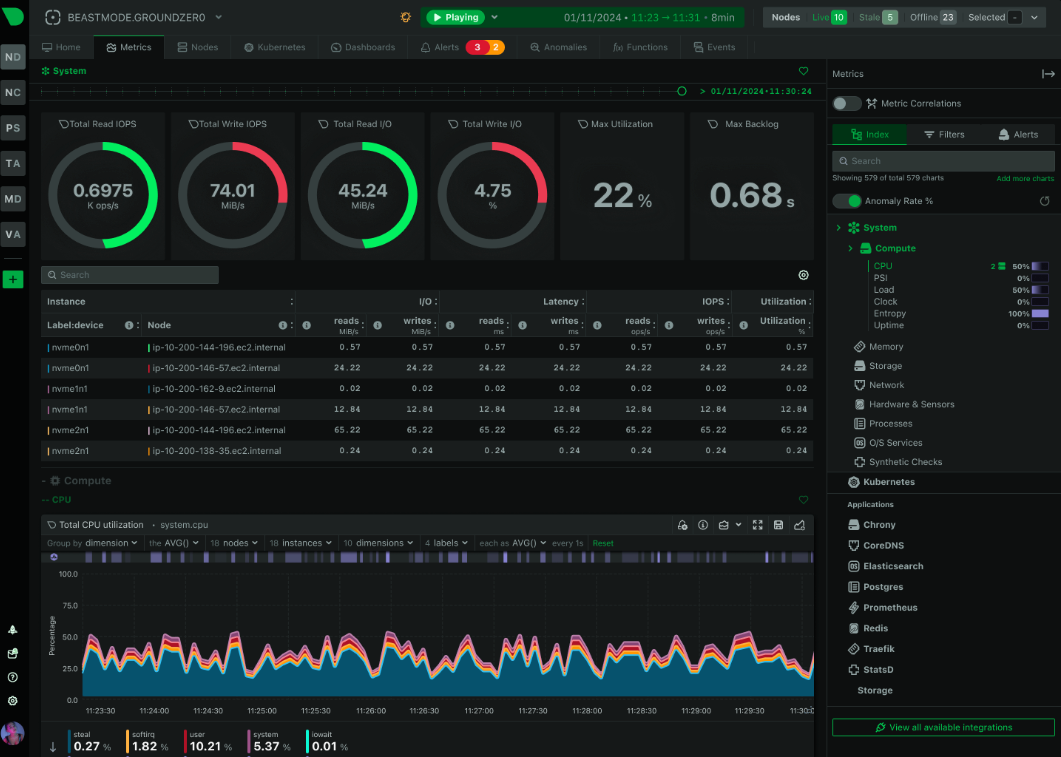
Our take: G2 reviewers highlight near zero-config setup and per-second dashboards that speed up troubleshooting. The gaps they mention are weaker Windows support, no full APM and limited long-term retention without the paid cloud tiers.
Pricing
Agent: free and open source (GPLv3+). Netdata Cloud: Community free (up to 5 nodes) · Homelab $90/yr (unlimited nodes, non-commercial, fair usage) · Business $4.50/node/mo billed annually or $6/node/mo monthly (p90 node billing) · Enterprise On-Premises custom (from 200 nodes). 14-day Business trial (as of September 2026).
| Pros | Cons |
|---|---|
| Per-second resolution reveals transient spikes missed by minute-level tools | Long-term retention requires Netdata Cloud or external TSDB export |
| On-agent ML anomaly detection – no data sent externally | Community cloud tier limited to 5 nodes |
| Local-by-default storage – no central database required for single-host monitoring | Centralized management and SSO require paid Netdata Cloud tiers |
| Netdata Parents enable multi-host aggregation without a separate TSDB | Less suited for APM – focused on host and container infrastructure metrics |
25. Centreon: best for Nagios-compatible distributed monitoring
Centreon is an open-source monitoring platform that provides real-time performance visibility across physical, virtual, and cloud server environments. It tracks CPU, memory, and disk usage with detailed, customizable dashboards. Monitoring Connectors (formerly Plugin Packs), 700+ pre-built, vendor-validated monitoring templates, are available for hundreds of technologies and, in our assessment, significantly reduce time to first alert when onboarding new devices. Centreon’s distributed poller architecture allows lightweight pollers to be deployed in remote network segments while all data is centralized in a single interface. All editions, including the open-source one, run Centreon Engine, an open-source fork of Nagios, so Nagios-compatible plugins work without modification. Commercial editions add Centreon MAP (dynamic topology and service maps that reflect live monitoring status), business and SLA monitoring, MBI reporting, and vendor support.
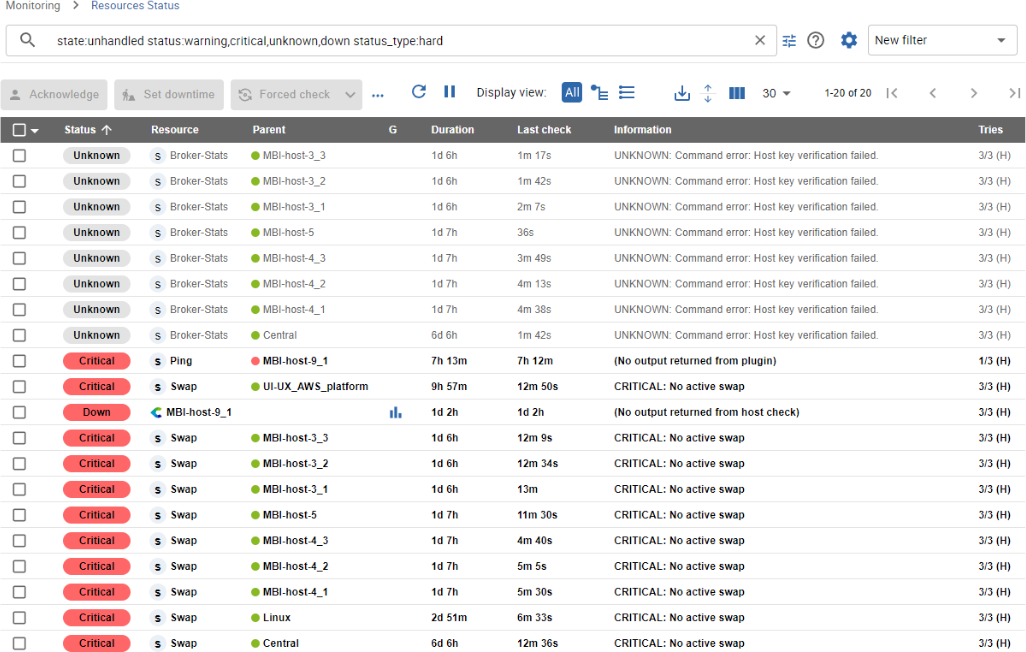
Our take: G2 reviewers find Centreon clean and intuitive once it’s running, with strong alerting and well-rated support. The complaints are complex configuration and an initial rollout that takes time and skill.
Pricing
Open source edition: free. Self-hosted IT 100: free up to 100 hosts. SaaS (annual): IT Edition from €3.40/host/mo (€425/mo for 125 hosts, free trial) · Pro Edition from €4.50/host/mo (€1,125/mo for 250 hosts, quote required). Self-hosted IT Edition from €2.27/host/mo; Business and MSP from €4.53/host/mo (as of September 2026).
| Pros | Cons |
|---|---|
| Monitoring Connectors – 700+ pre-built templates | Configuration is complex and needs monitoring expertise |
| Distributed pollers for remote segments with centralized data | Full feature set (MAP, MBI) fragmented across paid add-ons |
| Centreon MAP generates live topology and service maps | Most active forums are French language; smaller English community |
| All editions run Nagios-compatible plugins unmodified | Initial setup requires monitoring experience; not plug-and-play |
Choosing the Right Server Monitoring Tool
After reviewing all 25 tools, our takeaway is that the server monitoring market is mature and competitive. Narrowing down your options requires an honest assessment of your environment and operational requirements. Here are the questions we’d use to guide your evaluation:
Do you need external monitoring, agent-based monitoring, or both? External tools like Dotcom-Monitor measure availability and performance as your users experience them. Agent-based tools like Zabbix, Prometheus, or Checkmk collect host-level metrics from inside the server. In our experience, many production environments benefit from both, which is why Dotcom-Monitor pairs its external checks with agent-based infrastructure monitoring through its MetricsView collector.
What does your infrastructure look like? On-premises, cloud, hybrid, and containerized environments have different coverage requirements. We recommend confirming that any tool you evaluate supports your specific stack before committing.
What is your team’s operational maturity? Open-source tools like Zabbix, Prometheus, Icinga, and Nagios Core offer tremendous flexibility but require hands-on setup and ongoing maintenance. From what we’ve seen, commercial SaaS platforms like Site24x7, Datadog, Dynatrace, or LogicMonitor reduce that operational overhead significantly.
How does pricing scale with your growth? Per-device, per-user, per-sensor, and consumption-based models all behave differently at scale. Our advice is to calculate your expected costs at 2× and 5× your current device count before selecting a tool.
Whatever direction you choose, our experience is that proactive monitoring is consistently less costly than reactive incident response. The right tool makes it possible to find and fix problems before your users ever notice them.
Frequently Asked Questions
Free, open-source software with no time limit: Prometheus, Nagios Core, Icinga 2, Zabbix, LibreNMS, Uptime Kuma, the Netdata agent, Checkmk Community (up to ~100 hosts), the Centreon open-source edition, and the Pandora FMS open-source edition (up to 50 agents).
Permanent free tiers of commercial tools: Dotcom-Monitor Free (25 targets), Datadog Free (5 hosts, 1-day retention), New Relic Free (100 GB/mo ingest, 1 full platform user), Grafana Cloud Free, Site24x7 Free (50 resources), Sensu Go Free (up to 100 nodes), Netdata Cloud Community (up to 5 nodes), WhatsUp Gold Free Edition (10 devices), PRTG freeware (100 sensors), ManageEngine OpManager Free (3 devices), and Nagios XI Free Edition (7 nodes or 100 services).
Time-limited trials only: Dynatrace (15 days), AppDynamics (15 days), LogicMonitor (15 days), NinjaOne (14 days), and SolarWinds (30 days). Dotcom-Monitor offers both a permanent free plan and a 30-day full-feature trial. All limits as of September 2026.
Synthetic monitoring simulates user interactions from external locations, checking that your site loads, APIs respond correctly, and user journeys complete. It measures what a user experiences. Infrastructure monitoring collects resource metrics from inside the server: CPU, memory, disk, and processes. The two are complementary. A server can have healthy resource metrics while serving a broken user experience, and synthetic monitoring catches that. Most production environments benefit from both running in parallel.
We'd look at three scenarios. Cloud-native / Kubernetes: Prometheus + Grafana Cloud free tier (zero cost, no backend to manage). Low ops overhead: the free Netdata agent for instant per-second visibility, or Site24x7 Lite at $9/month for a managed all-in-one experience. External uptime: Dotcom-Monitor's free plan (25 targets, $0 forever) or a self-hosted Uptime Kuma instance shows whether your site and APIs are reachable. We'd avoid Nagios Core, Zabbix, or Icinga without a dedicated ops person, because the configuration overhead is high relative to what small teams need.
Yes. Datadog, Dynatrace, New Relic, and Site24x7 run agents on on-premises servers and cloud VMs alike, and LogicMonitor's collectors cover both, aggregating everything into one dashboard. SolarWinds SAM and ManageEngine OpManager support hybrid environments from a self-hosted deployment. For open-source teams, Prometheus with remote_write to Thanos or Mimir handles multi-site well; Zabbix proxies collect from segmented or remote networks. One caveat we'd flag: if on-premises servers lack outbound internet access, SaaS-based tools won't work, so a self-hosted or proxy-based architecture is required.
Common starting points we recommend for general-purpose servers: CPU: warning at 80% sustained for 5 minutes, critical at 95%. Memory: warning at 85%, critical at 95%; monitor swap usage separately as an earlier warning sign. Disk: warning at 80% used, critical at 90%; for log-heavy servers, alert earlier or monitor fill rate rather than percentage. Tools with AI anomaly detection, such as Dynatrace (Davis), Datadog (Watchdog), LogicMonitor (Edwin AI), New Relic (Applied Intelligence), and Netdata (on-agent ML), learn normal behavior and alert on deviations automatically, reducing the need for manual thresholds.
