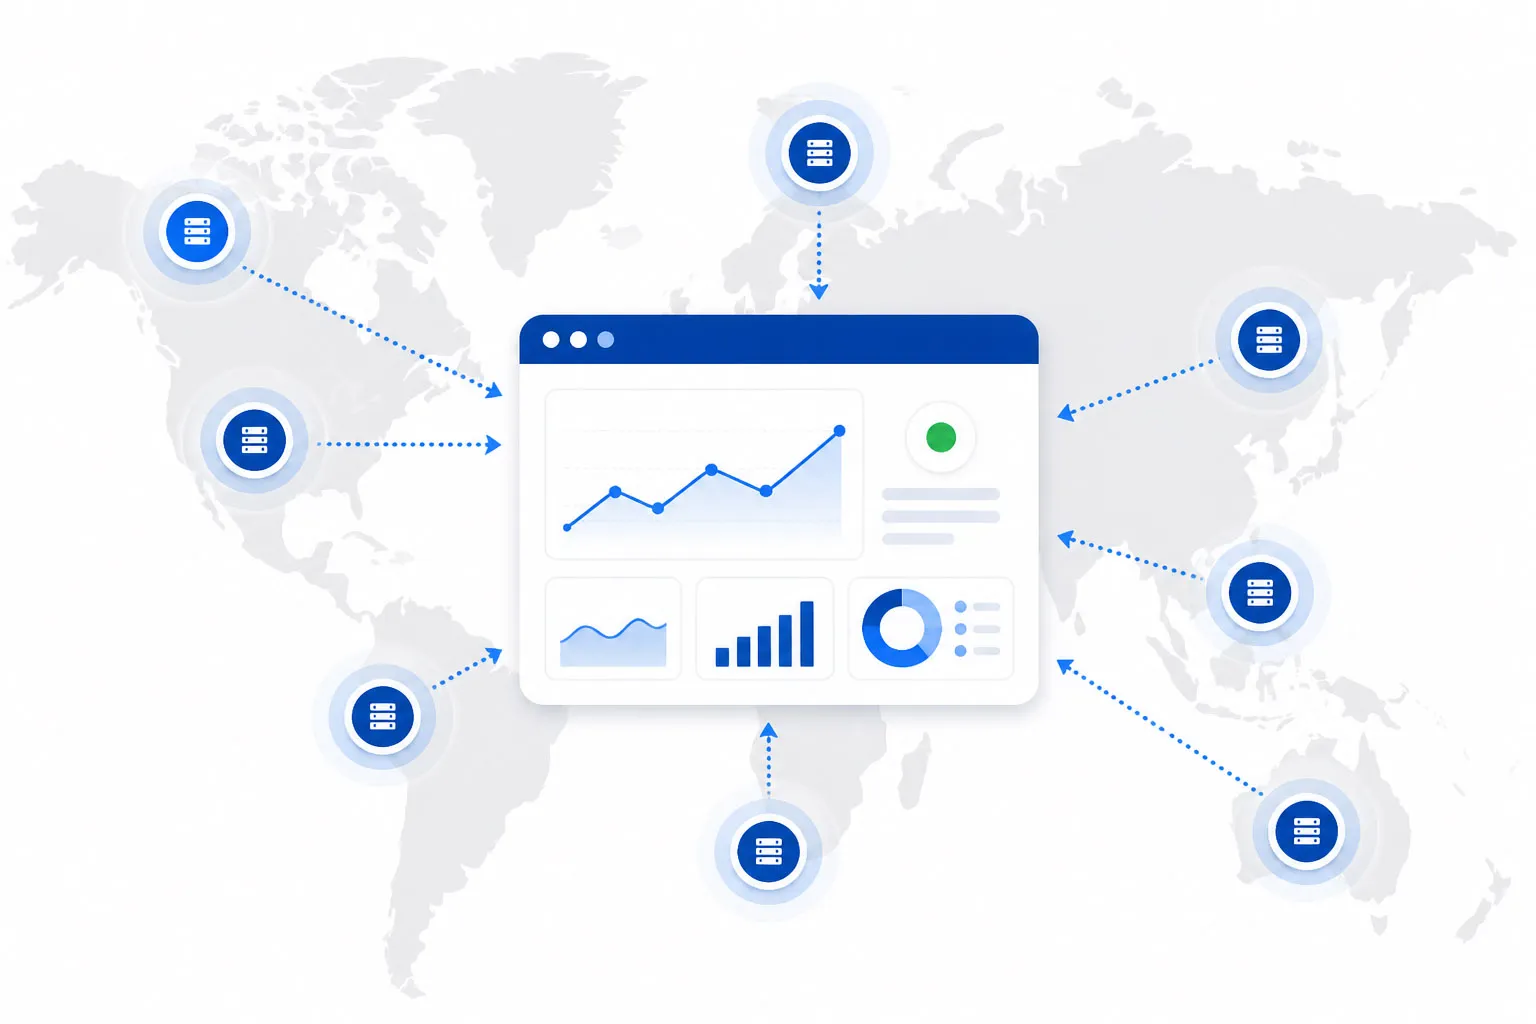
Synthetic monitoring is the practice of running scripted, automated checks against a website, application or application programming interface (API) from locations outside your network, on a fixed schedule, to verify that it is available, fast and working correctly, whether or not any real users are online.
Because synthetic monitoring doesn’t wait for traffic, you catch outages, slow pages and broken logins before customers do, at any hour and from any region. This page covers how it works, the main test types, how it compares with other approaches, and where it falls short.
What Is Synthetic Monitoring?
Synthetic monitoring is an active monitoring method that uses scripts to simulate what a user or client does, such as loading a page, signing in or calling an API, and runs those scripts on a schedule from external locations. Each run records whether every step succeeded and how long it took.
You will also see it called active, outside-in or black-box monitoring. Google’s Site Reliability Engineering book defines black-box monitoring as testing a system’s externally visible behavior the way a user would see it, and calls it symptom-oriented: it tells you the system isn’t working right now.
The key word is scripted. Synthetic monitoring generates its own traffic on a schedule you set, so it produces data overnight, in quiet regions and before launch. Passive methods only record what happens when real people use the site.
A simple example: a script signs in with a test account and loads the dashboard every 5 minutes from New York, Frankfurt and Singapore. If the dashboard fails from two of those cities, you get an alert before the first support ticket arrives.
How Does Synthetic Monitoring Work?
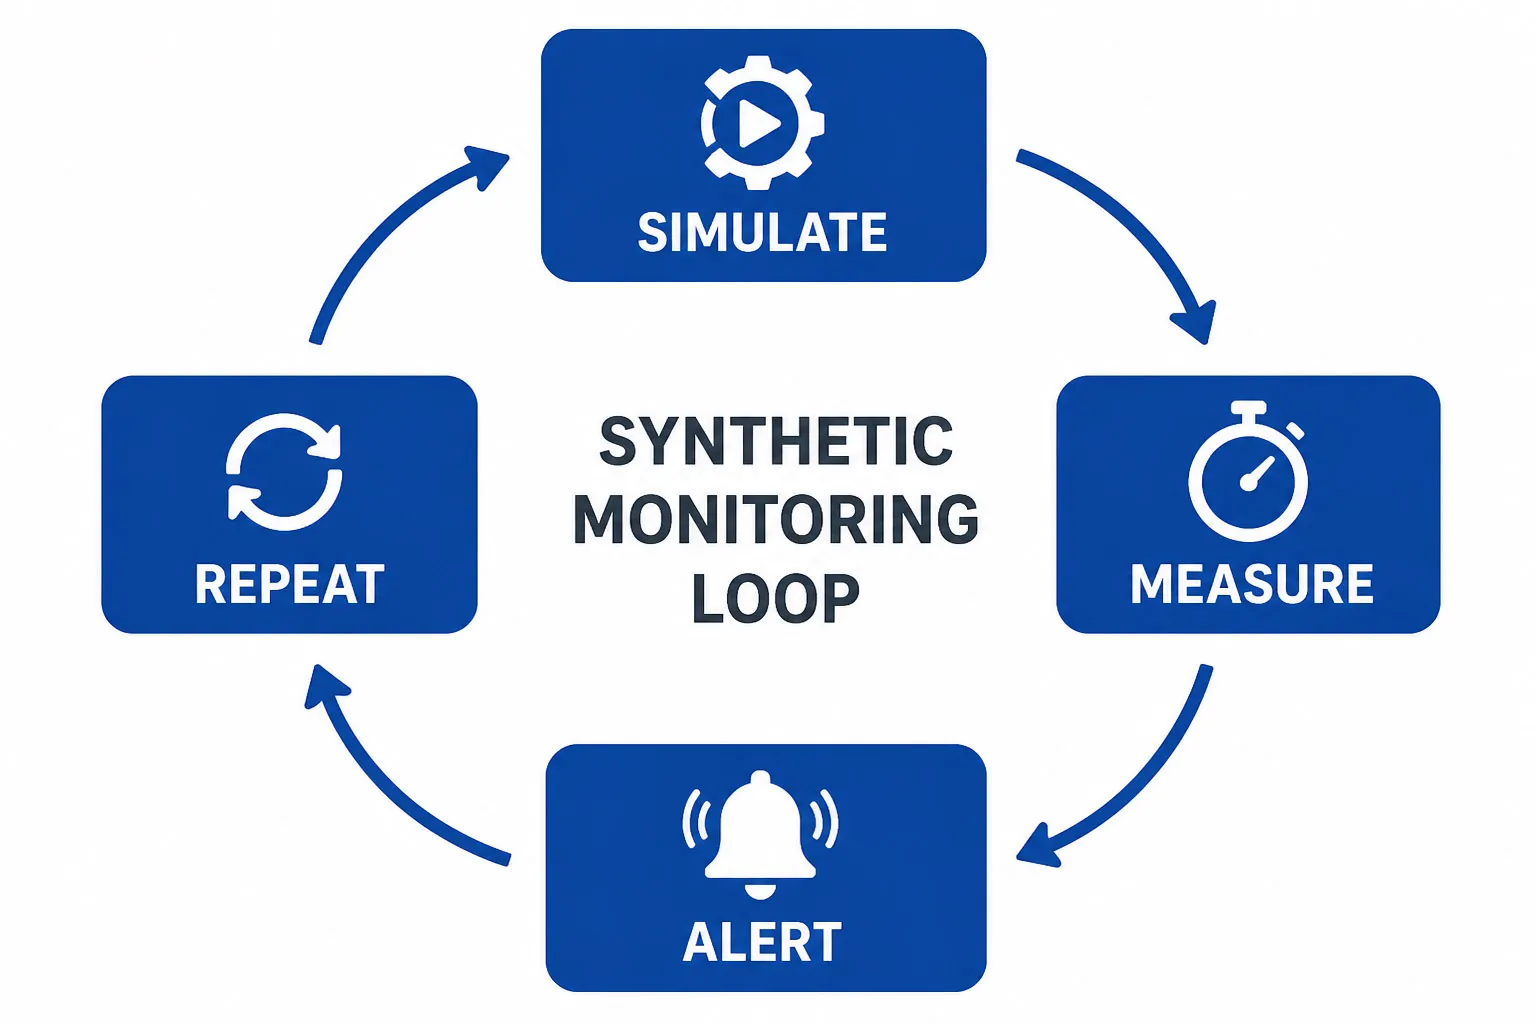
Every synthetic monitoring setup follows the same loop: decide what to test, script it, schedule it, measure it and alert on failures.
- Choose Journeys and Endpoints. Start with whatever costs you revenue or breaks a service level agreement (SLA) when it fails: sign-in, checkout, search, a public API, Domain Name System (DNS) resolution and certificate validity.
- Script the Test. A simple check needs only a URL and an expected response. Multi-step journeys are recorded in a browser or written as code, with assertions that confirm each step returned the right content, not just a 200 status.
- Choose Locations and Frequency. Public monitoring locations (agents) on the internet measure the full path your users take, including DNS, content delivery network (CDN) and internet service provider (ISP) routing. Private agents inside your network cover internal apps and staging. Frequency sets how quickly you can detect a failure.
- Run and Measure. Each run records availability, response time and step timings and, for browser tests, page load metrics, waterfall data and screenshots. Repeated runs under the same conditions give you a stable baseline.
- Alert and Diagnose. When a check fails or crosses a threshold, the tool notifies on-call staff by email, chat or paging tools. The recorded run shows which step failed, from where and how long it took, which shortens diagnosis.
Then the loop repeats every interval, around the clock. Shorter intervals reduce mean time to detect (MTTD), at the cost of more runs and more alerts to tune.
Types of Synthetic Tests
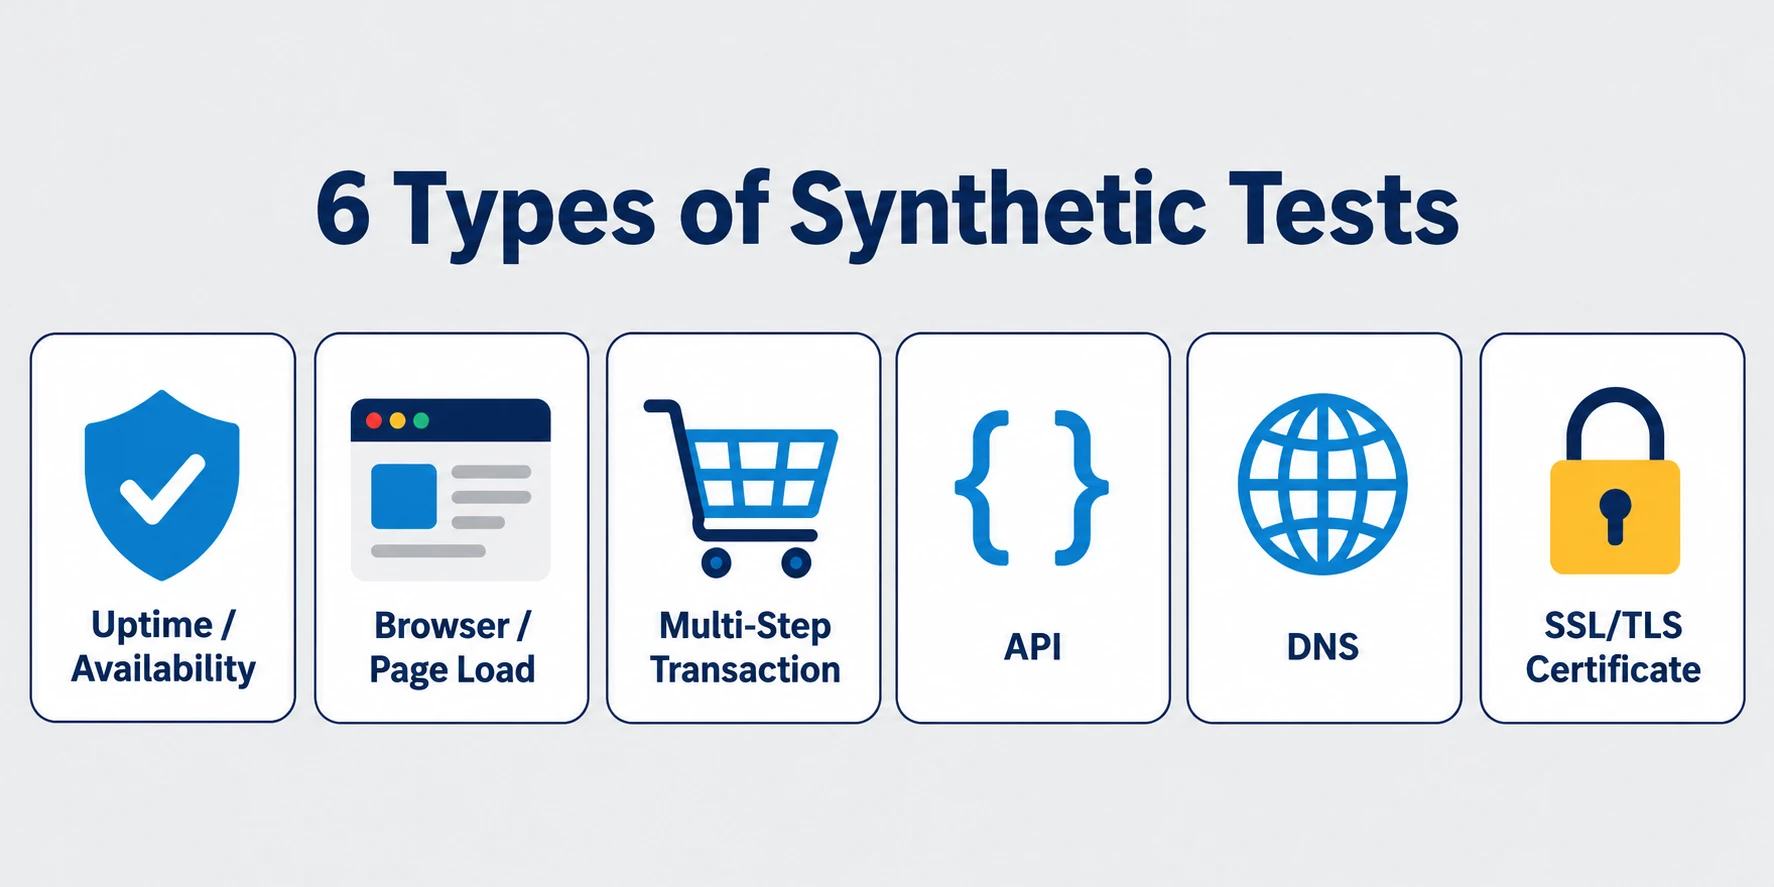
Most synthetic monitoring setups combine several test types, because each one validates a different layer of the stack.
| Test Type | What It Checks | Example Failure It Catches | Suggested Starting Interval |
|---|---|---|---|
| Uptime / availability (HTTP, ping, port) | Whether a URL, host or port responds with the expected status and content | Web server returns 503 errors after a bad deploy | Every 1 minute for critical endpoints; every 5 minutes for lower-priority checks |
| Browser / page load | A full page render in a real browser, including JavaScript and third-party resources | A third-party script blocks rendering and page load doubles | Every 5 minutes for key pages; every 15 minutes for secondary pages |
| Multi-step transaction | A scripted user journey, step by step | The “Place order” button stops responding after a UI change | Every 5 minutes for critical journeys; consider 1 minute when faster detection is necessary |
| API | Status code, latency and response payload, including chained calls | Token endpoint returns 200 with an empty body | Every 1 or 5 minutes, according to the endpoint’s importance |
| DNS | Name resolution, resolution time and record values | An A record still points to a retired server after a migration | Every 1 minute for critical records; every 5–15 minutes for lower-priority records |
| SSL/TLS certificate | Certificate validity, expiry date and chain | A certificate on a forgotten subdomain expires | Every 15 minutes as a starting configuration; shorten the interval for critical endpoints |
These intervals are starting recommendations, not measured averages or a fixed schedule for every service. They use the configurable intervals described in Dotcom-Monitor’s frequency documentation, its frequency and location guidance, and the criticality guidance on the DNS monitoring page. The 15-minute certificate interval is an example configuration, not an expiry-detection guarantee. Choose a shorter interval when certificate failures would interrupt a critical service, and configure an advance expiry warning. Available intervals depend on the monitoring platform and plan.
A scheduled interval is not a guaranteed alert time. A long-running browser script must finish or time out, and failure verification and notification filters can add delay.
Transaction tests are the most valuable and the most fragile. They replay a real journey, such as search, add to cart and pay, so they catch failures an uptime check misses: the home page loads, but nobody can buy. See our guide to transaction monitoring for scripting details.
API tests send requests and check status codes, latency and the response body. Multi-step API tests chain calls, for example authenticate, create a record, read it back and delete it, to validate a whole workflow. Read more about API monitoring.
Protocol checks apply the same approach to email (SMTP, POP3, IMAP), FTP and VoIP services, and mobile app synthetic monitoring extends it to native apps.
Synthetic Monitoring vs. Real User Monitoring vs. APM
Synthetic monitoring tests your application with scripted traffic on a schedule, real user monitoring (RUM) records what actual visitors experience, and application performance monitoring (APM) traces what happens inside your code. The difference is who generates the traffic: synthetic creates its own, while RUM and APM depend on real requests arriving.

| Comparison | Synthetic | RUM | APM |
|---|---|---|---|
| Data source | Scripted checks from agents | Real sessions (JavaScript snippet) | Backend instrumentation (traces, logs) |
| When it collects | 24/7, on a schedule | Only when users are active | During real requests |
| Works before launch | Yes | No | Yes, in staging |
| Low-traffic periods | Full coverage | Sparse data | Fewer samples |
| Catches unscripted paths | No | Yes | Partly |
| Best for | Uptime, regressions, SLA evidence | Real experience across devices and networks | Root cause in code |
- Use synthetic monitoring when you need to know a critical journey works right now, including overnight, in new regions or before a release.
- Use RUM when you need to see what real visitors on real devices and networks actually experience.
- Use APM when you know something is slow and need to find the service, query or code path responsible.
Most teams combine all three: synthetic monitoring tells you something broke, RUM tells you who it affected, and APM tells you why.
Which Metrics Should You Track?
Track a small set of synthetic monitoring metrics that cover availability, speed and how fast you find problems.
| Metric | What It Tells You |
|---|---|
| Uptime % | Share of checks that passed; the basis for SLA and service level objective (SLO) reports |
| Response time / Time to First Byte (TTFB) | How fast the server starts answering; a rising TTFB points to backend or network trouble |
| Page load and Largest Contentful Paint (LCP) | When the page, and its main content, become visible |
| Cumulative Layout Shift (CLS) | How much the layout jumps while it loads |
| Total Blocking Time (TBT) | How long the main thread is blocked during load |
| Transaction step duration | Which step in a journey is slow or failing |
| Error rate by location | Whether a failure is global or limited to one region, network or CDN edge |
| Mean time to detect (MTTD) | How long a failure lasts before an alert fires |
One common mistake: Interaction to Next Paint (INP), the Core Web Vital for responsiveness, can’t be measured reliably in a synthetic (lab) test, because it depends on real user interactions. web.dev recommends Total Blocking Time as the lab proxy for INP; get INP itself from RUM field data.
Example: Malcolm Group’s Checkout Monitoring
A Malcolm Group case study published in 2019 shows why checking a complete purchase journey matters. The company reported checkout failures involving third-party scripts, coupons, carts and payment processing, despite its stores remaining accessible.
Michael Roebuck, identified in the case study as VP of Marketing & Operations, described an EveryStep script that opened a store page, selected an option, checked text, added products and verified the cart total. It then applied a coupon, checked the revised price and submitted checkout using a card expected to be declined. The script looked for the decline message to verify that the payment step responded.
Roebuck reported running the checkout check every 15 minutes, with alerts identifying the failed part of the process.
“I want confirmation that our processes are running.”
— Michael Roebuck, Malcolm Group, in the published case study
This is a documented monitoring setup, rather than a timed incident reconstruction. It illustrates the difference between checking that a storefront responds and checking that the steps needed to place an order work.
Benefits and Limitations
Synthetic monitoring is strongest at telling you, quickly and consistently, that a known path is broken. It is weakest at everything you didn’t script.
Benefits
- You Can Detect Failures Before Users Report Them. Scheduled checks can reveal a broken login or checkout without waiting for a support ticket. Detection and notification time depend on the check interval, script duration, failure verification and alert filters.
- You Get 24/7 and Pre-Launch Coverage. Checks run overnight, during quiet periods and against staging, so you can validate a release before real traffic hits it.
- You Get Consistent Baselines for SLAs. The same script from the same locations produces comparable numbers over time, which makes uptime reports and vendor disputes much easier.
- You Can Test Regions Without Traffic. Launching in a new market? Run checks from there before your first real visitor arrives.
Limitations
- Synthetic Monitoring Only Covers Scripted Paths. Journeys, devices and edge cases you didn’t script go unchecked.
- Scripts Need Maintenance. UI and selector changes break transaction scripts even when the app works. Our guide to writing maintainable monitoring scripts covers how to reduce that churn.
- Poor Tuning Causes False Alerts. A single network blip from one location can page someone at night if alert rules are too sensitive.
- It Doesn’t Reflect Real Device and Network Diversity. Monitoring locations run on stable data center connections, not congested mobile networks. Pair synthetic checks with RUM to see the real spread.
How to Get Started
You don’t need dozens of checks on day one to get value from synthetic monitoring. Five steps get most teams to useful coverage.
- Pick 3 to 5 Journeys That Carry Revenue or an SLA. Sign-in, checkout, your main API and your top landing page are typical first picks.
- Match Locations to Where Your Users Are. A pass from one US data center tells you little about users in Europe or Asia. See choosing check frequency and locations.
- Set Frequency by Criticality. Start with 5-minute checks for important browser journeys and 15-minute checks for secondary pages. Consider 1-minute checks when faster detection is necessary. For DNS, use 1-minute checks for critical records and 5–15 minutes for lower-priority records. A 15-minute certificate check is a starting configuration; shorten it for critical endpoints and alert ahead of expiry.
- Verify Failures and Configure Alert Filters. Keep False Positive Check enabled to recheck failed results. Dotcom-Monitor’s documented Default Filter requires confirmation from two locations when multiple locations are configured; a device using only one location bypasses that requirement. Review the filter’s location threshold and error duration against your detection needs. If a failure affecting only one region must trigger an alert, configure a suitable regional check rather than relying solely on two-location confirmation.
- Review Scripts After Every Release. A renamed button or new consent banner can break a script overnight. Running synthetic checks in CI/CD catches that before production does.
Once those are stable, add browser tests for key pages and expand to secondary journeys.
Try Synthetic Monitoring on Your Own Journeys
Dotcom-Monitor runs uptime, browser, transaction, API, DNS and SSL checks from public and private locations, with waterfalls and screenshots for browser-based checks. Record your first checkout or login script with EveryStep and see the results within minutes. Explore our synthetic monitoring software or start a free trial.
